 TokenSave
 Data · Index · v1.0
TokenSave Language Tax Index
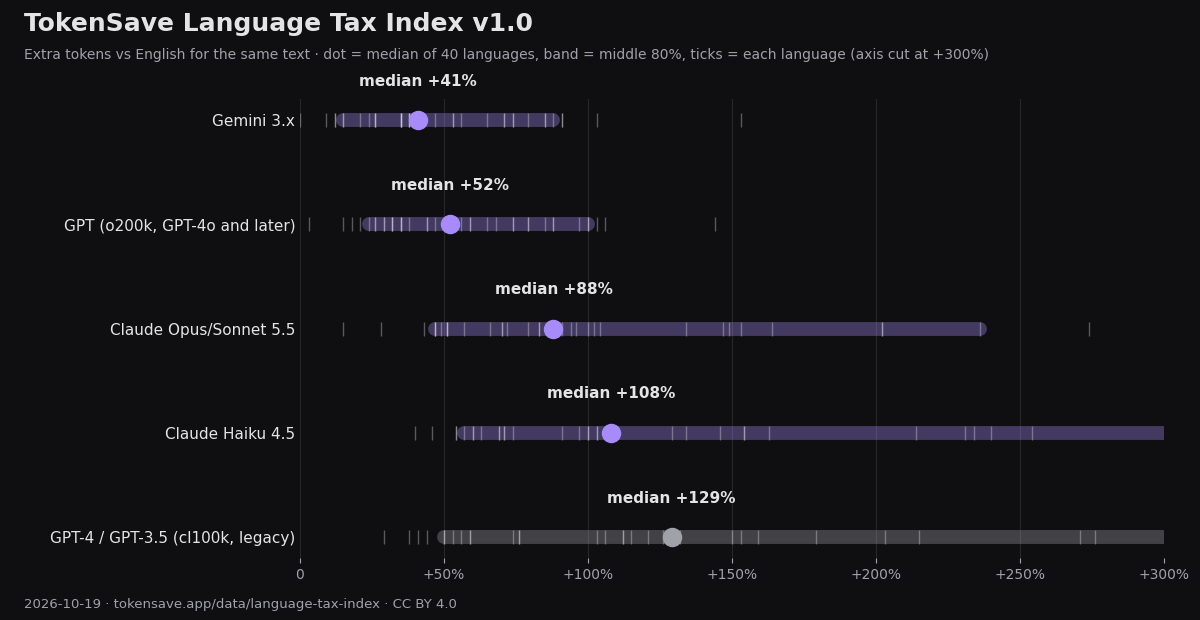
The “language tax” is how many more tokens the same text needs in your language than in English. On today's models the median across 40 languages is +41% on Gemini, +52% on GPT and +88% on Claude Opus/Sonnet 5.5. API prices, context windows and token-based limits all scale with it.
Version 1.0 · 2026-10-19 · 41 languages · 4 current tokenizers + 1 legacy · License CC BY 4.0 · Re-measured when new models ship
What the index shows
- Every model taxes non-English text, but by very different amounts. Gemini has the smallest median tax, Claude the largest. Korean is +41% on Gemini, +44% on GPT and +89% on Claude 5.5; Ukrainian +74%, +88% and +70%.
- The tax has fallen over time. On the legacy GPT-4 tokenizer (cl100k) the median was +129%; on the current o200k tokenizer it is +52%. Hindi went from +359% to +50%.
- A lower tax is not always a cheaper model. The index compares each language with English on the same model. Claude 5.5 also needs more tokens for English itself (47 for our prompt, against 34 on GPT and 34 on Gemini), and prices per token differ. Use the token calculator to compare real costs.
- It matters most for chat, documents and API work, much less for coding agents. In our coding test the prompt language moved input tokens by about 1%, because the agent's own instructions dwarf the prompt (data).
The index, all 41 languages
Extra tokens versus English on the same tokenizer. Sorted by GPT.
| Language | Gemini 3.x | GPT (o200k, GPT-4o and later) | Claude Opus/Sonnet 5.5 | Claude Haiku 4.5 | GPT-4 / GPT-3.5 (cl100k, legacy) |
|---|---|---|---|---|---|
| English | – | – | – | – | – |
| Chinese (Simplified) | ±0% | +3% | +15% | +54% | +53% |
| Indonesian | +9% | +15% | +70% | +60% | +38% |
| Spanish | +12% | +18% | +47% | +40% | +29% |
| Portuguese | +26% | +21% | +47% | +54% | +41% |
| Persian | +15% | +24% | +96% | +163% | +179% |
| Arabic | +41% | +26% | +89% | +154% | +203% |
| German | +35% | +26% | +102% | +91% | +50% |
| Dutch | +47% | +29% | +72% | +74% | +74% |
| French | +41% | +29% | +49% | +69% | +44% |
| Norwegian | +41% | +32% | +47% | +57% | +56% |
| Russian | +26% | +32% | +51% | +103% | +115% |
| Swedish | +38% | +32% | +43% | +46% | +50% |
| Chinese (Traditional) | +12% | +35% | +28% | +71% | +112% |
| Danish | +38% | +35% | +51% | +60% | +59% |
| Vietnamese | +26% | +35% | +87% | +134% | +132% |
| Italian | +38% | +38% | +66% | +63% | +59% |
| Finnish | +74% | +44% | +104% | +100% | +103% |
| Korean | +41% | +44% | +89% | +154% | +150% |
| Turkish | +35% | +47% | +91% | +106% | +106% |
| Hindi | +21% | +50% | +134% | +214% | +359% |
| Filipino | +56% | +53% | +79% | +71% | +76% |
| Romanian | +53% | +53% | +57% | +69% | +76% |
| Hebrew | +79% | +56% | +83% | +146% | +276% |
| Gujarati | +65% | +59% | +202% | +306% | +618% |
| Urdu | +41% | +59% | +147% | +231% | +324% |
| Marathi | +24% | +65% | +164% | +254% | +391% |
| Bengali | +15% | +68% | +202% | +306% | +509% |
| Hungarian | +88% | +74% | +87% | +97% | +126% |
| Thai | +35% | +74% | +153% | +240% | +271% |
| Japanese | +35% | +79% | +51% | +103% | +121% |
| Kannada | +71% | +79% | +577% | +809% | +835% |
| Malayalam | +91% | +85% | +351% | +506% | +909% |
| Polish | +71% | +88% | +100% | +109% | +112% |
| Ukrainian | +74% | +88% | +70% | +129% | +215% |
| Tamil | +53% | +97% | +274% | +403% | +747% |
| Czech | +85% | +100% | +83% | +100% | +159% |
| Slovak | +91% | +100% | +94% | +109% | +153% |
| Telugu | +85% | +103% | +236% | +351% | +838% |
| Greek | +103% | +106% | +149% | +234% | +394% |
| Punjabi | +153% | +144% | +572% | +803% | +641% |
Method
- Definition: tax = tokens for the language ÷ tokens for English on the same tokenizer − 1, rounded to a whole percent. The headline number is the median over the 40 non-English languages.
- Text: one everyday instruction (summarize a customer email and suggest a reply) translated into 41 languages. The prompts and raw counts are in the two source datasets: GPT tokenizers (DOI 10.5281/zenodo.23427148) and Claude, Gemini and GPT (DOI 10.5281/zenodo.23428350).
- Counting: GPT with tiktoken; Claude from Claude Code usage reports minus a one-character baseline; Gemini with the Google AI Studio token counter. Models that share a tokenizer share a column (Claude Opus and Sonnet 5.5 gave identical counts, as did Gemini 3.8 Flash and 3.1 Pro).
Update policy and version history
We re-measure the same 41 prompts when a model with a new tokenizer ships, add or replace its column, and publish a new version here with the date. Earlier versions stay in the history, so changes over time can be cited.
- v1.0 · 2026-10-19 · First release: 41 languages × 4 current tokenizers plus the legacy GPT-4 tokenizer, from our 2026-09-30 and 2026-10-17 measurements.
Queued for the next version: Claude Haiku 5.5 (released 2026-10-07).
Limitations
- Version 1.0 rests on one prompt. On other text the per-language numbers move by roughly ±10–20 percentage points; the ranking of models and languages is more stable. Adding more texts is planned for a later version.
- Input tokens only. Output in another language can cost more again, and prices per token differ by model.
- Claude counts come from usage reports and can be off by about ±2 tokens.
How to cite
Free to use, quote and republish with attribution under CC BY 4.0. Please link to this page.
TokenSave (2026). TokenSave Language Tax Index, version 1.0 (2026-10-19). https://tokensave.app/data/language-tax-index
Embed the chart
Related
- Source data: GPT tokenizers, 41 languages
- Source data: Claude, Gemini and GPT, 41 languages
- Does prompt language change coding cost?
- Count tokens for your own text
Questions or corrections: contact@jonhisking.com