 TokenSave
 Data · Dataset
How many tokens each language needs on Claude, Gemini and GPT
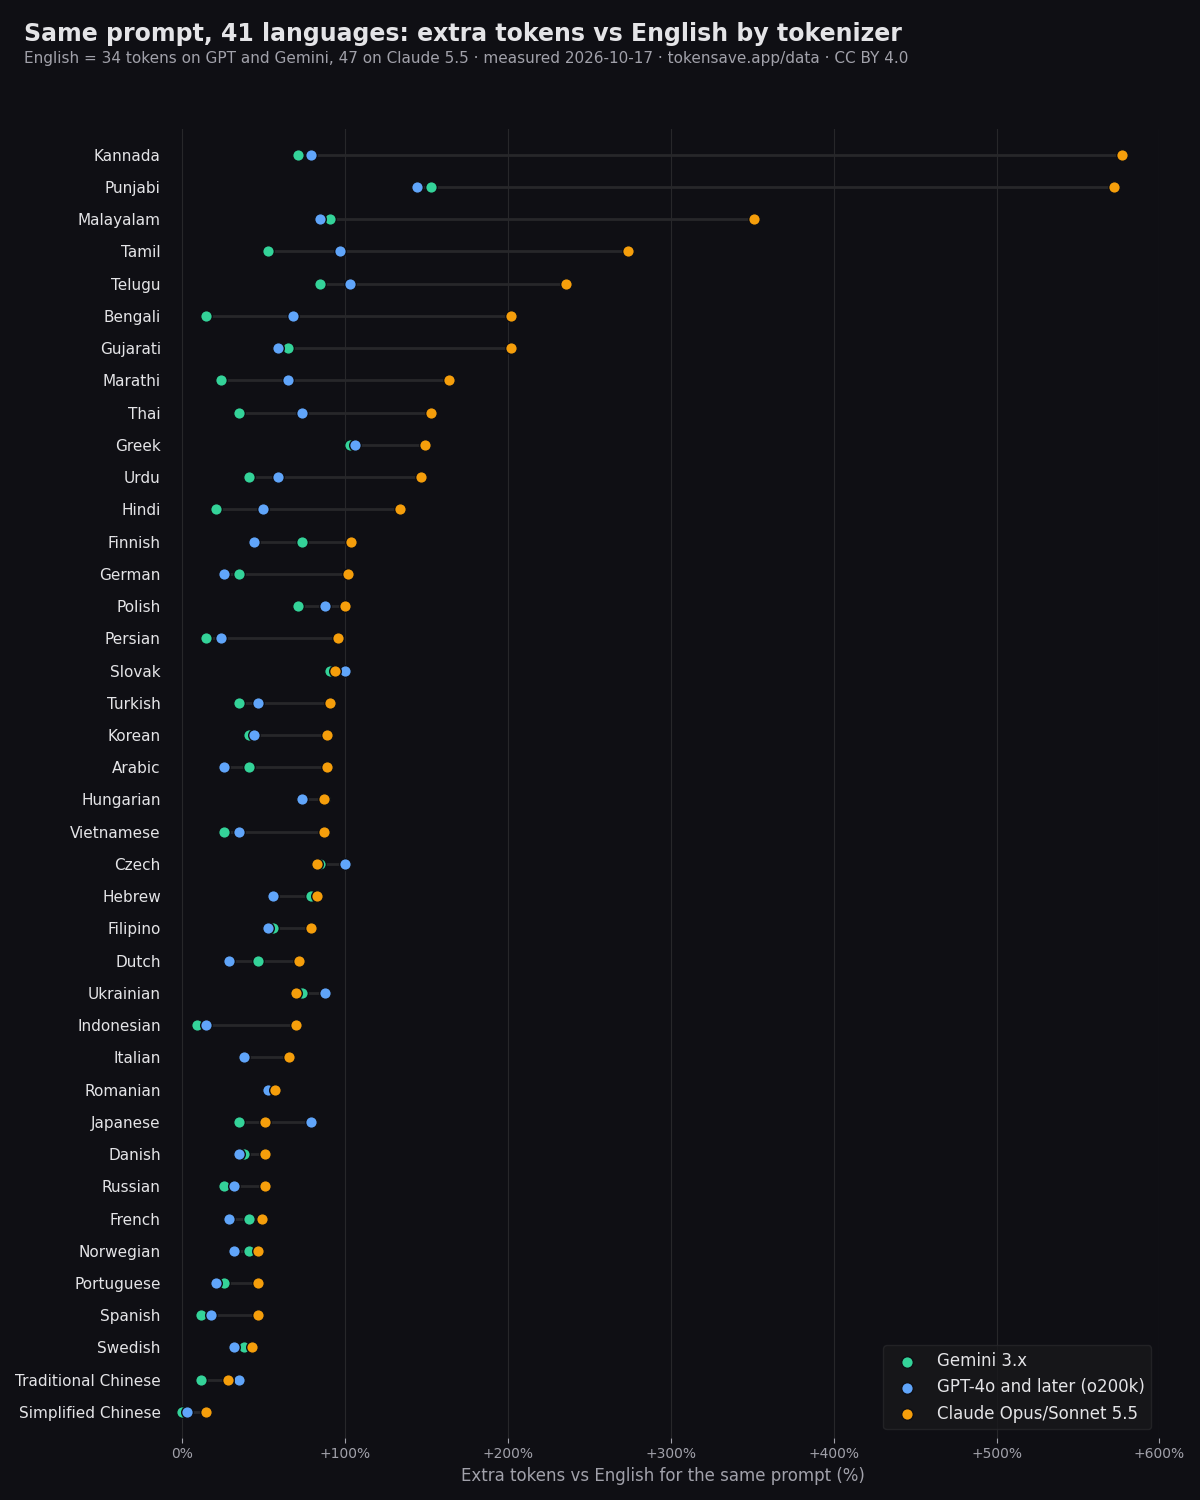
The same Korean prompt needs 89 tokens on Claude Opus/Sonnet 5.5, 49 on GPT and 48 on Gemini. Across 40 non-English languages, the median extra cost versus English is +41% on Gemini, +52% on GPT and +88% on Claude 5.5. The widest gap is Kannada: +577% on Claude 5.5 against +71% on Gemini.
Measured 2026-10-17 · 41 languages · 4 tokenizers · License CC BY 4.0 · Companion to the GPT-only dataset
DOI 10.5281/zenodo.23428350 · Also on Hugging Face · Kaggle · GitHub
Key findings
- English itself costs more on Claude 5.5. The English prompt is 47 tokens on Claude Opus/Sonnet 5.5, 35 on Claude Haiku 4.5, and 34 on both GPT and Gemini.
- Claude's newer tokenizer changed Latin-script text only. Compared with Haiku 4.5, Claude 5.5 needs 34% more tokens for English and more for every other Latin-script language, while Korean, Japanese, Chinese, Cyrillic, Arabic, Hebrew, Greek, Thai and the Indic languages have exactly the same counts. That is why the gap versus English looks smaller on Claude 5.5 (Korean +89%) than on Haiku 4.5 (Korean +154%).
- Indic languages are the costliest on Claude. Hindi is +134% on Claude 5.5 against +50% on GPT and +21% on Gemini.
- Gemini has the smallest gap overall. Simplified Chinese costs the same as English on Gemini (±0%).
- Models from the same family share counts. Claude Opus 5.5 and Sonnet 5.5 gave identical counts for all 41 languages; Gemini 3.8 Flash and 3.1 Pro matched on every language we re-checked.
All 41 languages
Tokens for the same prompt, with the difference versus English in brackets. Sorted by Claude 5.5.
| Language | Claude Opus/Sonnet 5.5 | Claude Haiku 4.5 | Gemini 3.x | GPT o200k |
|---|---|---|---|---|
| English | 47 (±0%) | 35 (±0%) | 34 (±0%) | 34 (±0%) |
| Chinese (Simplified) | 54 (+15%) | 54 (+54%) | 34 (±0%) | 35 (+3%) |
| Chinese (Traditional) | 60 (+28%) | 60 (+71%) | 38 (+12%) | 46 (+35%) |
| Swedish | 67 (+43%) | 51 (+46%) | 47 (+38%) | 45 (+32%) |
| Spanish | 69 (+47%) | 49 (+40%) | 38 (+12%) | 40 (+18%) |
| Portuguese | 69 (+47%) | 54 (+54%) | 43 (+26%) | 41 (+21%) |
| Norwegian | 69 (+47%) | 55 (+57%) | 48 (+41%) | 45 (+32%) |
| French | 70 (+49%) | 59 (+69%) | 48 (+41%) | 44 (+29%) |
| Russian | 71 (+51%) | 71 (+103%) | 43 (+26%) | 45 (+32%) |
| Japanese | 71 (+51%) | 71 (+103%) | 46 (+35%) | 61 (+79%) |
| Danish | 71 (+51%) | 56 (+60%) | 47 (+38%) | 46 (+35%) |
| Romanian | 74 (+57%) | 59 (+69%) | 52 (+53%) | 52 (+53%) |
| Italian | 78 (+66%) | 57 (+63%) | 47 (+38%) | 47 (+38%) |
| Indonesian | 80 (+70%) | 56 (+60%) | 37 (+9%) | 39 (+15%) |
| Ukrainian | 80 (+70%) | 80 (+129%) | 59 (+74%) | 64 (+88%) |
| Dutch | 81 (+72%) | 61 (+74%) | 50 (+47%) | 44 (+29%) |
| Filipino | 84 (+79%) | 60 (+71%) | 53 (+56%) | 52 (+53%) |
| Hebrew | 86 (+83%) | 86 (+146%) | 61 (+79%) | 53 (+56%) |
| Czech | 86 (+83%) | 70 (+100%) | 63 (+85%) | 68 (+100%) |
| Vietnamese | 88 (+87%) | 82 (+134%) | 43 (+26%) | 46 (+35%) |
| Hungarian | 88 (+87%) | 69 (+97%) | 64 (+88%) | 59 (+74%) |
| Arabic | 89 (+89%) | 89 (+154%) | 48 (+41%) | 43 (+26%) |
| Korean | 89 (+89%) | 89 (+154%) | 48 (+41%) | 49 (+44%) |
| Turkish | 90 (+91%) | 72 (+106%) | 46 (+35%) | 50 (+47%) |
| Slovak | 91 (+94%) | 73 (+109%) | 65 (+91%) | 68 (+100%) |
| Persian | 92 (+96%) | 92 (+163%) | 39 (+15%) | 42 (+24%) |
| Polish | 94 (+100%) | 73 (+109%) | 58 (+71%) | 64 (+88%) |
| German | 95 (+102%) | 67 (+91%) | 46 (+35%) | 43 (+26%) |
| Finnish | 96 (+104%) | 70 (+100%) | 59 (+74%) | 49 (+44%) |
| Hindi | 110 (+134%) | 110 (+214%) | 41 (+21%) | 51 (+50%) |
| Urdu | 116 (+147%) | 116 (+231%) | 48 (+41%) | 54 (+59%) |
| Greek | 117 (+149%) | 117 (+234%) | 69 (+103%) | 70 (+106%) |
| Thai | 119 (+153%) | 119 (+240%) | 46 (+35%) | 59 (+74%) |
| Marathi | 124 (+164%) | 124 (+254%) | 42 (+24%) | 56 (+65%) |
| Bengali | 142 (+202%) | 142 (+306%) | 39 (+15%) | 57 (+68%) |
| Gujarati | 142 (+202%) | 142 (+306%) | 56 (+65%) | 54 (+59%) |
| Telugu | 158 (+236%) | 158 (+351%) | 63 (+85%) | 69 (+103%) |
| Tamil | 176 (+274%) | 176 (+403%) | 52 (+53%) | 67 (+97%) |
| Malayalam | 212 (+351%) | 212 (+506%) | 65 (+91%) | 63 (+85%) |
| Punjabi | 316 (+572%) | 316 (+803%) | 86 (+153%) | 83 (+144%) |
| Kannada | 318 (+577%) | 318 (+809%) | 58 (+71%) | 61 (+79%) |
Method
- Same prompt and translations as our GPT dataset: “Please summarize the customer email below in three bullet points and suggest a polite reply. The customer says the order arrived two days late and one item was missing from the box.” in 41 languages. Every translated prompt is in the CSV.
- Claude: each prompt was sent through Claude Code (
claude -p) with a fixed one-line system prompt, and the input tokens it reported (uncached + cache read + cache write) were reduced by the same run with a one-character message. Re-running with a different system prompt, a different baseline character and a different order gave identical counts. - Gemini: the prompt token counter in Google AI Studio, which adds one start token (“a” shows 2, “a a a” shows 4); we subtracted it. Measured on Gemini 3.8 Flash and re-checked on Gemini 3.1 Pro.
- GPT: OpenAI's tiktoken with
o200k_base. - “vs English” = tokens in the language ÷ English tokens on the same tokenizer − 1, rounded to a whole percent.
Limitations
- One prompt. With other text the ratios move by roughly ±10–20 percentage points; the ranking is more stable than the exact numbers.
- Claude counts come from usage reports rather than a dedicated count endpoint, so each value can be off by about ±2 tokens (under 5 percentage points against English).
- Input text only; output length is not measured. Prices differ by model, so more tokens does not always mean a higher bill. Use the token calculator to compare costs.
How to cite
Free to use, quote and republish with attribution under CC BY 4.0. Please link to this page or the DOI.
TokenSave (2026). Token cost by language on Claude, Gemini and GPT: 41 languages measured [Data set]. Zenodo. https://doi.org/10.5281/zenodo.23428350
Embed the chart
Related
- GPT-only dataset with the older cl100k tokenizer
- Our Claude Korean test (input and output, in Korean)
- Count tokens for your own text
Questions or corrections: contact@jonhisking.com