 TokenSave
All comparisons · Prices checked 2026-10-14
Gemini 3.8 Flash vs Claude Haiku 4.5: API cost comparison
For a typical chatbot reply, Gemini 3.8 Flash costs $0.0026 and Claude Haiku 4.5 costs $0.0036 per request: Gemini 3.8 Flash is 27% cheaper. Gemini 3.8 Flash is cheaper in every workload below.
Newer model: Claude Haiku 5.5 costs $0.1 input and $0.5 output per 1M tokens, against $1 and $5 for Claude Haiku 4.5. See Claude Haiku 4.5 vs Claude Haiku 5.5.
API prices
| Gemini 3.8 Flash | Claude Haiku 4.5 | |
|---|---|---|
| Maker | Anthropic | |
| Input / 1M tokens | $0.75 | $1 |
| Output / 1M tokens | $3.75 | $5 |
| Output vs input price | +400% | +400% |
| Context window | 1.05M tokens | 200K tokens |
| Tokens for the same English text | baseline (GPT o200k count) | ~103% of GPT's count (estimate) |
Capability
On the Epoch Capabilities Index, Gemini 3.8 Flash scores 158.8 and Claude Haiku 4.5 142.8: Gemini 3.8 Flash is 16.1 points higher. See capability vs price for all models.
Capability scores: Epoch Capabilities Index by Epoch AI, used under CC BY 4.0.
Counting tokens for Claude? Use the Claude token counter: in our test Claude used 38% more tokens than GPT for the same English prompt (data).
Cost by workload
| Workload (per 1,000 requests) | Gemini 3.8 Flash | Claude Haiku 4.5 | Cheaper |
|---|---|---|---|
| Chatbot reply short question plus some chat history · 1,500 in / 400 out | $2.62 | $3.60 | Gemini 3.8 Flash 27% cheaper |
| Document Q&A (RAG) retrieved passages plus a question · 8,000 in / 500 out | $7.88 | $10.81 | Gemini 3.8 Flash 27% cheaper |
| Coding agent step large working context, short edit · 25,000 in / 800 out | $21.75 | $29.87 | Gemini 3.8 Flash 27% cheaper |
| Summarize a long report long input, short summary · 20,000 in / 300 out | $16.12 | $22.15 | Gemini 3.8 Flash 27% cheaper |
| Write an article short brief, long draft · 800 in / 2,000 out | $8.10 | $11.12 | Gemini 3.8 Flash 27% cheaper |
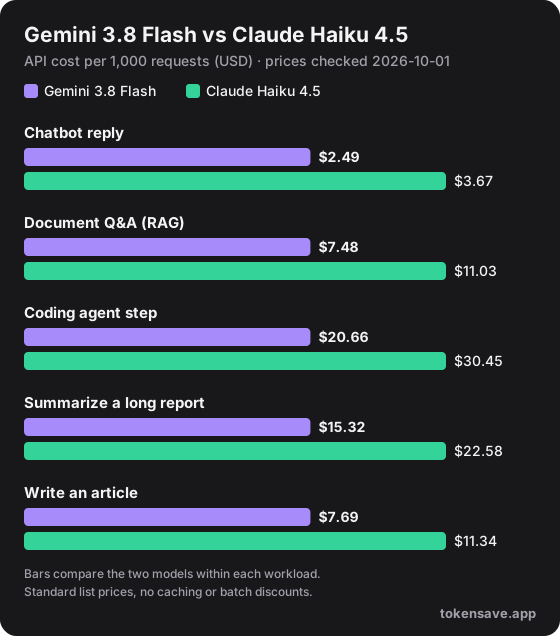
Gemini 3.8 Flash is cheaper on both input and output, so it costs less for every kind of request. It is 27% cheaper on input and 27% cheaper on output once the tokenizer difference is included.
Same text, different token counts. Each company uses its own tokenizer. By our estimate Claude Haiku 4.5 counts about 3% more tokens than Gemini 3.8 Flash for the same English text, and the costs above already include that. Paste your own prompt into the token counter to see both counts.
Monthly cost
| Monthly volume | Gemini 3.8 Flash | Claude Haiku 4.5 |
|---|---|---|
| 10,000 chatbot replies / month | $26.25 | $36.05 |
| 100,000 chatbot replies / month | $262 | $360 |
| 1,000,000 chatbot replies / month | $2,625 | $3,605 |
Calculate your own
Enter your typical request size and volume.
Token counts are for English text measured with GPT's tokenizer; each model's own tokenizer difference is applied automatically.
Questions
Which is cheaper, Gemini 3.8 Flash or Claude Haiku 4.5?
For a typical chatbot reply (1,500 input and 400 output tokens), Gemini 3.8 Flash costs $0.0026 and Claude Haiku 4.5 costs $0.0036 per request, so Gemini 3.8 Flash is 27% cheaper. Gemini 3.8 Flash is cheaper in every workload below.
How much do Gemini 3.8 Flash and Claude Haiku 4.5 cost per million tokens?
Gemini 3.8 Flash costs $0.75 per 1M input tokens and $3.75 per 1M output tokens. Claude Haiku 4.5 costs $1 input and $5 output. Prices checked 2026-10-14.
Do both models count the same text as the same number of tokens?
No. Each model family has its own tokenizer, so the same text can be a different number of tokens. The costs on this page already include that difference (estimated from GPT's tokenizer).
Related comparisons
- GPT-6 Luna vs Gemini 3.8 Flash
- GPT-6 Luna vs Claude Haiku 4.5
- Claude Haiku 4.5 vs Claude Sonnet 5.5
- Claude Haiku 4.5 vs Claude Haiku 5.5
Paste a real prompt to see its exact tokens and cost on Gemini 3.8 Flash, Claude Haiku 4.5 and 30+ other models.
Open the token counter →Standard API list prices, short-context tier, no caching or batch discounts. Prices change; check each provider's pricing page before large jobs.