 TokenSave
All comparisons · Prices checked 2026-10-14
GPT-6 Luna vs Gemini 3.8 Flash: API cost comparison
For a typical chatbot reply, GPT-6 Luna costs $0.0003 and Gemini 3.8 Flash costs $0.0026 per request: GPT-6 Luna is 87% cheaper. GPT-6 Luna is cheaper in every workload below.
API prices
| GPT-6 Luna | Gemini 3.8 Flash | |
|---|---|---|
| Maker | OpenAI | |
| Input / 1M tokens | $0.1 | $0.75 |
| Output / 1M tokens | $0.5 | $3.75 |
| Output vs input price | +400% | +400% |
| Context window | 922K tokens | 1.05M tokens |
| Tokens for the same English text | baseline (GPT o200k count) | baseline (GPT o200k count) |
Capability
On the Epoch Capabilities Index, GPT-6 Luna scores 156.4 and Gemini 3.8 Flash 158.8: Gemini 3.8 Flash is 2.4 points higher, within the margin of error. See capability vs price for all models.
Capability scores: Epoch Capabilities Index by Epoch AI, used under CC BY 4.0.
Cost by workload
| Workload (per 1,000 requests) | GPT-6 Luna | Gemini 3.8 Flash | Cheaper |
|---|---|---|---|
| Chatbot reply short question plus some chat history · 1,500 in / 400 out | $0.350 | $2.62 | GPT-6 Luna 87% cheaper |
| Document Q&A (RAG) retrieved passages plus a question · 8,000 in / 500 out | $1.05 | $7.88 | GPT-6 Luna 87% cheaper |
| Coding agent step large working context, short edit · 25,000 in / 800 out | $2.90 | $21.75 | GPT-6 Luna 87% cheaper |
| Summarize a long report long input, short summary · 20,000 in / 300 out | $2.15 | $16.12 | GPT-6 Luna 87% cheaper |
| Write an article short brief, long draft · 800 in / 2,000 out | $1.08 | $8.10 | GPT-6 Luna 87% cheaper |
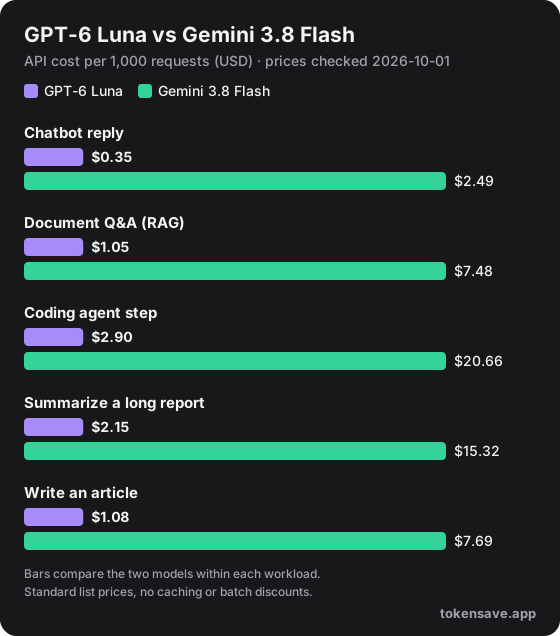
GPT-6 Luna is cheaper on both input and output, so it costs less for every kind of request. It is 87% cheaper on input and 87% cheaper on output.
Every GPT-6 model and rate, including cached input, the long-prompt tier and Batch: GPT-6 API pricing.
Monthly cost
| Monthly volume | GPT-6 Luna | Gemini 3.8 Flash |
|---|---|---|
| 10,000 chatbot replies / month | $3.50 | $26.25 |
| 100,000 chatbot replies / month | $35.00 | $262 |
| 1,000,000 chatbot replies / month | $350 | $2,625 |
Calculate your own
Enter your typical request size and volume.
Token counts are for English text measured with GPT's tokenizer; each model's own tokenizer difference is applied automatically.
Questions
Which is cheaper, GPT-6 Luna or Gemini 3.8 Flash?
For a typical chatbot reply (1,500 input and 400 output tokens), GPT-6 Luna costs $0.0003 and Gemini 3.8 Flash costs $0.0026 per request, so GPT-6 Luna is 87% cheaper. GPT-6 Luna is cheaper in every workload below.
How much do GPT-6 Luna and Gemini 3.8 Flash cost per million tokens?
GPT-6 Luna costs $0.1 per 1M input tokens and $0.5 per 1M output tokens. Gemini 3.8 Flash costs $0.75 input and $3.75 output. Prices checked 2026-10-14.
Do both models count the same text as the same number of tokens?
No. Each model family has its own tokenizer, so the same text can be a different number of tokens. The costs on this page already include that difference (estimated from GPT's tokenizer).
Related comparisons
- GPT-6 Luna vs GPT-6 Sol
- GPT-6 Luna vs Claude Haiku 4.5
- Gemini 3.8 Flash vs Claude Haiku 4.5
- DeepSeek V4.1 Flash vs GPT-6 Luna
- GPT-6 Luna vs Claude Haiku 5.5
Paste a real prompt to see its exact tokens and cost on GPT-6 Luna, Gemini 3.8 Flash and 30+ other models.
Open the token counter →Standard API list prices, short-context tier, no caching or batch discounts. Prices change; check each provider's pricing page before large jobs.