 TokenSave
OpenAI API Pricing 2026: GPT-6 Astra, Sol and Luna Costs
Jonhisking · October 2, 2026 · Updated October 15, 2026
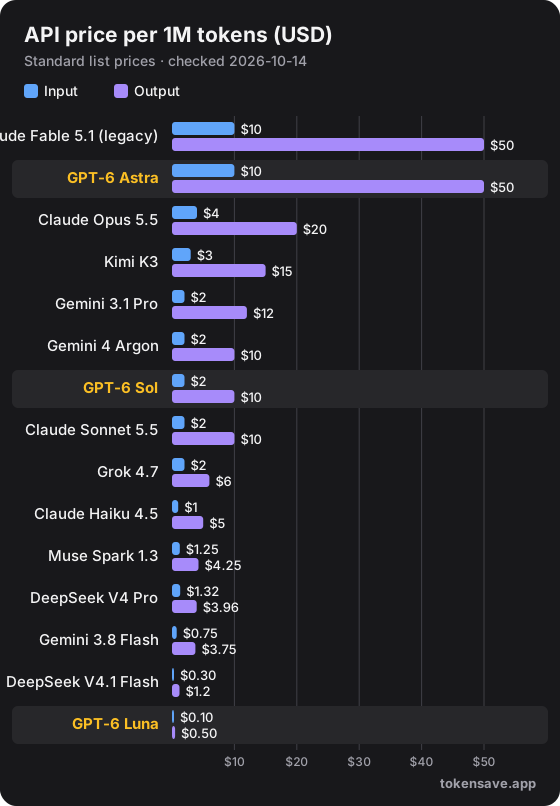
GPT-6 API pricing per 1M tokens is $0.10 input and $0.50 output for GPT-6 Luna, $2 and $10 for both GPT-6 Sol and GPT-6.1 Sol, $10 and $50 for GPT-6 Astra, and $12 and $60 for GPT-6.1 Sol Ultrafast, so GPT-6 Luna is the cheapest OpenAI GPT-6 API: 95% less than Sol. Below: every price dimension, what real requests and a month of traffic cost, how GPT-6 compares with Claude and Gemini, and which model to call.
OpenAI released GPT-6 Astra on September 3, 2026, GPT-6 Sol and GPT-6 Luna on September 22, GPT-6.1 Sol on September 29, and the Ultrafast mode of GPT-6.1 Sol on October 8.
GPT-6 API pricing (per 1M tokens)
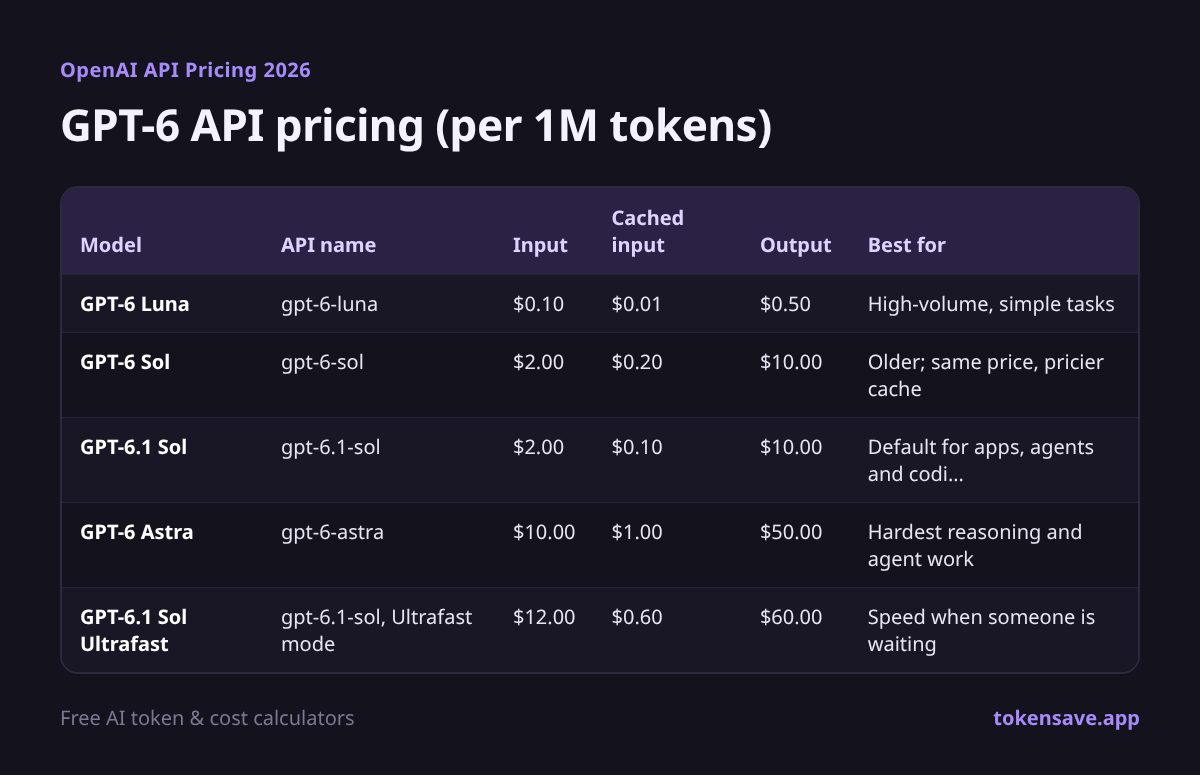
OpenAI's standard API prices, in US dollars per million tokens:
| Model | API name | Input | Cached input | Output | Best for |
|---|---|---|---|---|---|
| GPT-6 Luna | gpt-6-luna |
$0.10 | $0.01 | $0.50 | High-volume, simple tasks |
| GPT-6 Sol | gpt-6-sol |
$2.00 | $0.20 | $10.00 | Older; same price, pricier cache |
| GPT-6.1 Sol | gpt-6.1-sol |
$2.00 | $0.10 | $10.00 | Default for apps, agents and coding |
| GPT-6 Astra | gpt-6-astra |
$10.00 | $1.00 | $50.00 | Hardest reasoning and agent work |
| GPT-6.1 Sol Ultrafast | gpt-6.1-sol, Ultrafast mode |
$12.00 | $0.60 | $60.00 | Speed when someone is waiting |
Per 1,000 tokens, that is $0.0001 in and $0.0005 out on Luna, $0.002 and $0.01 on Sol, and $0.01 and $0.05 on Astra.
- The model you pick is the biggest price lever. Luna costs 95% less than Sol, and Sol costs 80% less than Astra.
- Output costs 400% more than input on every GPT-6 model, and hidden reasoning tokens are billed as output.
- Cached input is 90% off on Luna, GPT-6 Sol and Astra, and 95% off on GPT-6.1 Sol.
- Ultrafast is a mode, not a model. It costs 500% more than standard GPT-6.1 Sol and 20% more than Astra. See GPT-6.1 Sol Ultrafast pricing.
The rates above are OpenAI's. The long-prompt tier, Batch, Flex and Priority, Astra Ultrafast and web search prices further down come from LiteLLM's price list (October 15, 2026), because we could not load OpenAI's page for this update; confirm them on OpenAI's pricing page.
GPT-6 Sol vs GPT-6.1 Sol: which to call
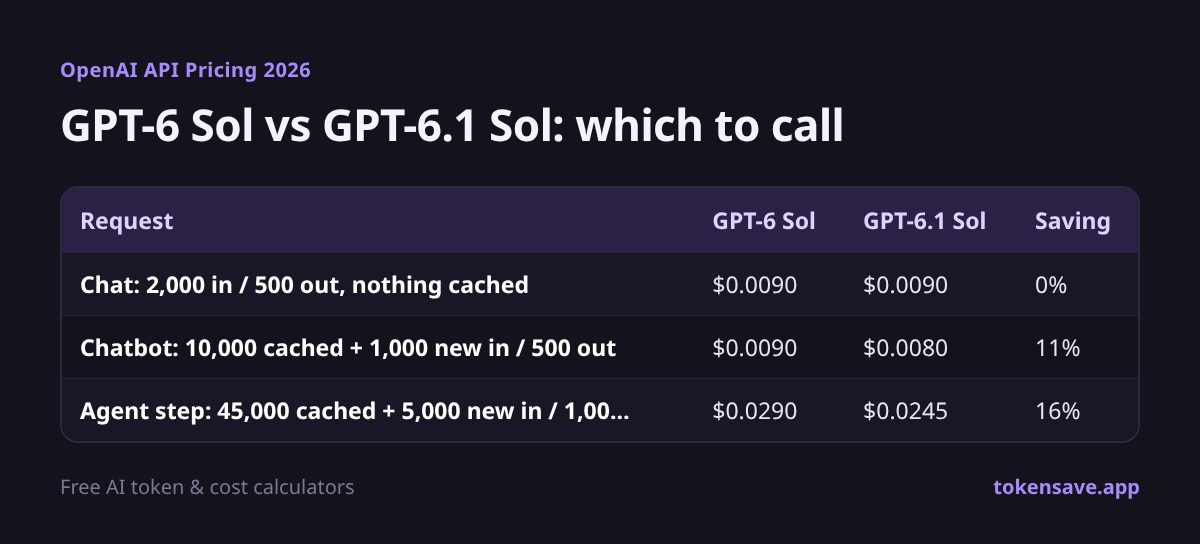
GPT-6.1 Sol arrived one week after GPT-6 Sol at the same list price, $2 input and $10 output. The only price change is cached input, which fell from $0.20 to $0.10 per million. According to OpenAI, 6.1 Sol is also better at coding, agent work and factual accuracy: 6.4 points higher on the DeepSWE coding benchmark and about 32% fewer factual errors at low reasoning effort.
| Request | GPT-6 Sol | GPT-6.1 Sol | Saving |
|---|---|---|---|
| Chat: 2,000 in / 500 out, nothing cached | $0.0090 | $0.0090 | 0% |
| Chatbot: 10,000 cached + 1,000 new in / 500 out | $0.0090 | $0.0080 | 11% |
| Agent step: 45,000 cached + 5,000 new in / 1,000 out | $0.0290 | $0.0245 | 16% |
Call GPT-6.1 Sol. A one-off request costs the same, and anything that resends instructions, documents or history costs 11% to 16% less. LiteLLM lists identical Batch, Flex and Priority prices for both. Keep gpt-6-sol only for a prompt tuned to it that you haven't re-tested. Full breakdown: GPT-6.1 Sol API pricing.
GPT-6.1 Sol also has two faster modes, at the prices OpenAI listed when we checked for our Ultrafast article on October 9:
| GPT-6.1 Sol mode | Input | Cached input | Output | Chat request (2,000 / 500) |
|---|---|---|---|---|
| Standard | $2 | $0.10 | $10 | $0.009 |
| Fast | $4 | $0.20 | $20 | $0.018 |
| Ultrafast | $12 | $0.60 | $60 | $0.054 |
OpenAI says Ultrafast runs up to 700% faster than standard Sol; pay for it only when a person is waiting. In Codex and ChatGPT Work, individuals need the Pro 500 plan for it.
GPT-6 Luna: the cheapest GPT-6 API
If you want a cheap GPT-6 API, this is it: $0.10 per million input tokens, $0.01 cached and $0.50 output. A chat request of 2,000 input and 500 output tokens costs $0.00045, so 10,000 cost $4.50, against $90 on GPT-6.1 Sol.
| Model | Input / output per 1M | 1 request (2,000 / 500) | 10,000 requests |
|---|---|---|---|
| GPT-6 Luna, Batch or Flex* | $0.05 / $0.25 | $0.000225 | $2.25 |
| GPT-5 nano | $0.05 / $0.40 | $0.00030 | $3.00 |
| GPT-6 Luna | $0.10 / $0.50 | $0.00045 | $4.50 |
| Claude Haiku 5.5 | $0.10 / $0.50 | $0.00062 | $6.21 |
| GPT-6.1 Sol | $2 / $10 | $0.0090 | $90 |
*Batch and Flex prices per LiteLLM's price list (October 15, 2026); confirm on OpenAI's pricing page. The Haiku 5.5 row allows for Claude's tokenizer, which counted about 38% more tokens for the same English text in our test (dataset).
- Only GPT-5 nano is cheaper at standard rates, and Luna through Batch or Flex undercuts it for work that can wait. See the cheapest LLM APIs, ranked.
- Claude Haiku 5.5 has the same list price but costs about 38% more per request because of the token count.
- Use Luna for classification, extraction, routing, tagging, short answers and short summaries. It is also what the ChatGPT Free plan runs in Codex.
- Move up to Sol for longer writing, multi-step reasoning and anything Luna gets wrong; a failed answer plus a retry costs more than starting on Sol.
Head to head: GPT-6 Luna vs GPT-6 Sol · GPT-6 Luna vs Gemini 3.8 Flash · DeepSeek V4 Flash vs GPT-6 Luna.
GPT-6 Astra pricing
GPT-6 Astra, the flagship, costs $10 per million input tokens, $1 cached and $50 output: 400% more than Sol. A 2,000 / 500 chat request costs $0.045.
| GPT-6 Astra | Input | Cached input | Output |
|---|---|---|---|
| Standard | $10 | $1 | $50 |
| Prompt over 272K tokens* | $20 | $2 | $75 |
| Batch or Flex* | $5 | – | $25 |
| Priority* | $20 | – | $100 |
| Ultrafast* | $60 | $6 | $300 |
*Per LiteLLM's price list (October 15, 2026); confirm on OpenAI's pricing page. LiteLLM gives no cached price for Batch, Flex or Priority.
- Astra Ultrafast is listed at 500% more than standard Astra. Our Codex pricing article found an Ultrafast mode for Astra on Pro 500; the API price is LiteLLM's.
- Astra vs 6.1 Sol Ultrafast: on a cache-heavy agent step (below), Astra costs $0.145 and 6.1 Sol Ultrafast $0.147, so the choice is intelligence or speed.
- When Astra pays off: long agent runs, hard reasoning and tasks where a wrong answer is expensive. Send only those to Astra.
Head to head: GPT-6 Sol vs GPT-6 Astra · GPT-6 Astra vs Claude Opus 5.5 · GPT-6 Astra vs Claude Fable 5.1.
Long prompts: the 272K-token tier
LiteLLM lists a 922,000-token maximum input for every GPT-6 model, but once a prompt passes 272,000 input tokens, the whole request is billed at a higher rate. Per LiteLLM's price list (October 15, 2026), input and cached input cost 100% more and output 50% more; our GPT-6.1 Sol article reported the same surcharge from OpenAI's page on October 6. Confirm on OpenAI's pricing page.
| Model, prompt over 272K | Input | Cached input | Output |
|---|---|---|---|
| GPT-6 Luna | $0.20 | $0.02 | $0.75 |
| GPT-6 Sol | $4 | $0.40 | $15 |
| GPT-6.1 Sol | $4 | $0.20 | $15 |
| GPT-6 Astra | $20 | $2 | $75 |
The jump is steep. On GPT-6.1 Sol, a 250,000-token document with a 2,000-token answer costs $0.52; a 300,000-token document costs $1.23, 137% more for 20% more input. On Astra the same two cost $2.60 and $6.15. Near the line, trim the document, split it, or retrieve only the relevant parts.
Batch, Flex and Priority
GPT-6 has three more processing tiers. Input / output per million tokens, per LiteLLM's price list (October 15, 2026); confirm on OpenAI's pricing page:
| Model | Batch | Flex | Standard | Priority |
|---|---|---|---|---|
| GPT-6 Luna | $0.05 / $0.25 | $0.05 / $0.25 | $0.10 / $0.50 | $0.20 / $1.00 |
| GPT-6 Sol | $1 / $5 | $1 / $5 | $2 / $10 | $4 / $20 |
| GPT-6.1 Sol | $1 / $5 | $1 / $5 | $2 / $10 | $4 / $20 |
| GPT-6 Astra | $5 / $25 | $5 / $25 | $10 / $50 | $20 / $100 |
- Batch: 50% off. Upload a file of requests and collect results later, typically within 24 hours. Good for tagging, bulk summaries and evaluations. See Batch APIs: half-price AI.
- Flex: also 50% off. Check OpenAI's docs for how its speed and availability differ before using it for anything a user waits on.
- Priority: 100% more, for traffic where speed matters more than cost.
- Web search: LiteLLM lists the web search tool at $10 per 1,000 calls on every GPT-6 model.
What a request really costs
Three common requests at standard rates. These are calculations from the list prices, not measurements:
- Chat reply: 2,000 input tokens (instructions, history and the question) and 500 output tokens, nothing cached.
- RAG question: 20,000 input tokens of retrieved passages plus the question, and 500 output tokens. The passages change with every question, so nothing is cached.
- Coding-agent step: 50,000 input tokens, 45,000 of them cached (instructions, files and earlier steps), and 1,000 output tokens. A task here is 30 such steps.
| Model | Chat reply | RAG question | Agent step | Agent task (30 steps) |
|---|---|---|---|---|
| GPT-6 Luna | $0.00045 | $0.00225 | $0.00145 | $0.04 |
| GPT-6 Sol | $0.0090 | $0.045 | $0.0290 | $0.87 |
| GPT-6.1 Sol | $0.0090 | $0.045 | $0.0245 | $0.74 |
| GPT-6 Astra | $0.045 | $0.225 | $0.145 | $4.35 |
| GPT-6.1 Sol Ultrafast | $0.054 | $0.27 | $0.147 | $4.41 |
The agent step on GPT-6.1 Sol: 5,000 new input tokens at $2 per million ($0.010), 45,000 cached at $0.10 ($0.0045) and 1,000 output at $10 ($0.010), for $0.0245.
- Input can outweigh output. In the RAG question, input is 89% of the cost on Sol, even though each output token costs 400% more.
- Caching changes agent costs. Without the cache, the agent step would cost $0.11 on GPT-6.1 Sol; caching takes 78% off.
- The task column is a rough guide. Real steps grow as a session gets longer, and higher reasoning effort adds output.
To price your own prompt, paste it into the token counter or the OpenAI token counter. For agents, try the coding agent cost calculator.
Monthly cost at 1,000 / 10,000 / 100,000 requests
The chat reply above (2,000 in / 500 out) at three monthly volumes:
| Model | 1,000 requests | 10,000 requests | 100,000 requests |
|---|---|---|---|
| GPT-6 Luna, Batch* | $0.23 | $2.25 | $22.50 |
| GPT-6 Luna | $0.45 | $4.50 | $45 |
| GPT-6.1 Sol, Batch* | $4.50 | $45 | $450 |
| GPT-6 Sol or GPT-6.1 Sol | $9 | $90 | $900 |
| GPT-6 Astra | $45 | $450 | $4,500 |
| GPT-6.1 Sol Ultrafast | $54 | $540 | $5,400 |
*Batch prices per LiteLLM's price list (October 15, 2026); confirm on OpenAI's pricing page.
For the 20,000-token RAG question, 100,000 requests a month cost $225 on Luna, $4,500 on Sol and $22,500 on Astra.
GPT-6 vs Claude and Gemini
At list price, GPT-6 matches Anthropic tier for tier. Input / output per million tokens, from each provider's pricing page as checked for our Claude token cost article on October 11, 2026 (Gemini 3.1 Pro is a preview model; the price is for prompts up to 200K tokens):
| Tier | OpenAI | Claude | |
|---|---|---|---|
| Cheapest | GPT-6 Luna: $0.10 / $0.50 | Haiku 5.5: $0.10 / $0.50 | – |
| Mid | GPT-6.1 Sol: $2 / $10 | Sonnet 5.5: $2 / $10 | Gemini 3.1 Pro: $2 / $12 |
| Top | GPT-6 Astra: $10 / $50 | Fable 5.1: $10 / $50 | – |
| Between | – | Opus 5.5: $4 / $20 | – |
The same price per token doesn't give the same bill: in our own measurement Claude turned the same English text into about 38% more tokens than GPT, and Gemini into about the same number (dataset). The 2,000 / 500 chat request, counted by each tokenizer:
| Model | 1 request | 10,000 requests |
|---|---|---|
| GPT-6 Luna | $0.00045 | $4.50 |
| Claude Haiku 5.5 | $0.00062 | $6.21 |
| GPT-6.1 Sol | $0.0090 | $90 |
| Gemini 3.1 Pro | $0.0100 | $100 |
| Claude Sonnet 5.5 | $0.0124 | $124 |
| Claude Opus 5.5 | $0.0248 | $248 |
| GPT-6 Astra | $0.045 | $450 |
| Claude Fable 5.1 | $0.0621 | $621 |
- Claude Sonnet 5.5 costs about 38% more per request than GPT-6.1 Sol, and Gemini 3.1 Pro about 11% more.
- GPT-6 Astra costs about 81% more per request than Claude Opus 5.5, and Claude Fable 5.1 about 38% more than Astra.
- Cost per token isn't cost per task. Models spend different numbers of tokens on the same job; test on your own prompts.
All 22 models: LLM API pricing compared. Head to head: GPT-6 Sol vs Claude Sonnet 5.5 · GPT-6.1 Sol vs Claude Sonnet 5.5 · Gemini 3.1 Pro vs GPT-6 Sol.
How to cut your GPT-6 API bill
- Route by difficulty. Start on Luna, escalate hard or failed requests to 6.1 Sol and only the hardest to Astra. At 100,000 chat requests, 80% on Luna and 20% on 6.1 Sol costs $216 against $900 all on Sol: 76% less.
- Move to GPT-6.1 Sol. Same list price as GPT-6 Sol, with a 50% lower cache price. If you are still on GPT-5.6 Sol ($4 / $20), switching cuts the per-token price by 50%; moving from GPT-5.6 Luna ($0.20 / $1.20) to GPT-6 Luna cuts input by 50% and output by 58%. See GPT-5.6 vs GPT-6 Sol.
- Cache everything that repeats. Fixed instructions, tools and documents first, the changing part last; cached reads are 90% to 95% off. See Prompt caching explained.
- Batch work that can wait. Batch and Flex are 50% off, per LiteLLM's list.
- Keep output and reasoning short. Reasoning tokens are billed as output. Use the lowest reasoning effort that works. See Reasoning models and cost.
- Stay under 272K tokens per prompt.
- Skip Priority and Ultrafast unless someone is waiting.
- Prompt in English if you can. On the GPT tokenizer, Korean uses about 44% more tokens and Japanese 79% more. See token cost by language.
For your own coding, a ChatGPT plan can beat the API: Codex includes GPT-6 Luna on Free and the full GPT-6 line from Plus ($20 a month). Compare in Codex pricing and the subscription vs API calculator.
FAQ
How much does the GPT-6 API cost? Per million tokens: GPT-6 Luna $0.10 input and $0.50 output, GPT-6 Sol and GPT-6.1 Sol $2 and $10, GPT-6 Astra $10 and $50, and GPT-6.1 Sol Ultrafast $12 and $60. Cached input is $0.01, $0.20, $0.10, $1 and $0.60 respectively.
What is the cheapest GPT-6 API? GPT-6 Luna, at $0.10 input and $0.50 output per million tokens: about $0.00045 for a 2,000-token prompt with a 500-token answer. Per LiteLLM's price list, Batch and Flex bring that down to $0.05 and $0.25.
Is GPT-6.1 Sol more expensive than GPT-6 Sol? No. Both cost $2 input and $10 output per million tokens. GPT-6.1 Sol's cached input is cheaper, $0.10 against $0.20, so it costs the same or less on every request.
How much does GPT-6 Astra cost? $10 per million input tokens, $1 cached and $50 output, 400% more than Sol: about $0.045 for a typical chat request. Per LiteLLM, prompts over 272,000 tokens cost $20 / $75 and Batch $5 / $25.
Does GPT-6 cost more for long prompts? Yes. Per LiteLLM's price list, once a prompt passes 272,000 input tokens the whole request is billed 100% more for input and 50% more for output, on every GPT-6 model.
Is GPT-6 cheaper than Claude? At list price they tie: Luna matches Haiku 5.5, 6.1 Sol matches Sonnet 5.5 and Astra matches Fable 5.1. Per request GPT-6 usually costs less, because Claude turned the same English text into about 38% more tokens in our test.
Core prices from our checks of OpenAI's pricing page, October 2–11, 2026; long-prompt, Batch, Flex, Priority and web search figures from LiteLLM's price list, October 15, 2026.
Sources
- OpenAI: API pricing
- OpenAI: API docs pricing
- LiteLLM: model prices and context windows (GitHub)
- OpenAI: Introducing GPT-6 Sol and Luna
- OpenAI: Introducing GPT-6.1 Sol
- OpenAI: GPT-6 Astra model page
- OpenAI: GPT-6 Sol model page
- OpenAI: GPT-6 Luna model page
- Claude API pricing
- Gemini API pricing
- Our related posts: GPT-6.1 Sol API pricing · GPT-6.1 Sol Ultrafast pricing · Claude token cost · The cheapest LLM APIs · Codex pricing
More articles
- Claude Haiku vs Opus for Coding: 330 Measured Runs
- Claude Code Cache Lasts 1 Hour: What a Break Costs (Measured)
- Prompting in Korean, Japanese or Hindi? How to Cut the Token Cost
- Context Windows Explained: Why Long Chats Get Worse and Cost More
- Codex Usage Limits (Oct 2026): Messages per 5 Hours, Measured
Paste a prompt to see its tokens and cost on every GPT-6 model, Claude and Gemini.
Open the token counter →