 TokenSave
LLM API Pricing Compared: 22 Models From GPT-6 to Claude, Gemini and DeepSeek
Jonhisking · October 2, 2026
There are now dozens of language models with public API prices, and 10,000 of the same request can cost $3 on one and $450 on another. This page lists the current list prices of 22 popular models from OpenAI, Anthropic, Google, xAI, DeepSeek, Mistral, Alibaba and Moonshot side by side, with what a typical request actually costs, and how to choose.
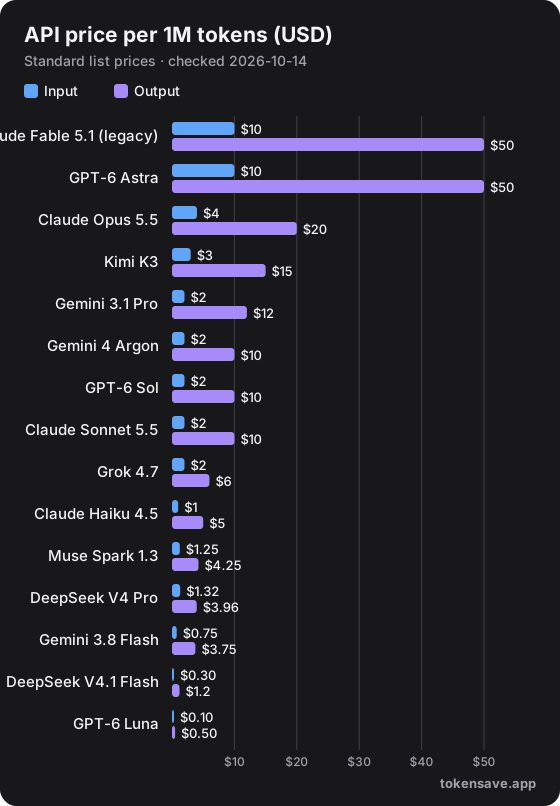
API prices compared
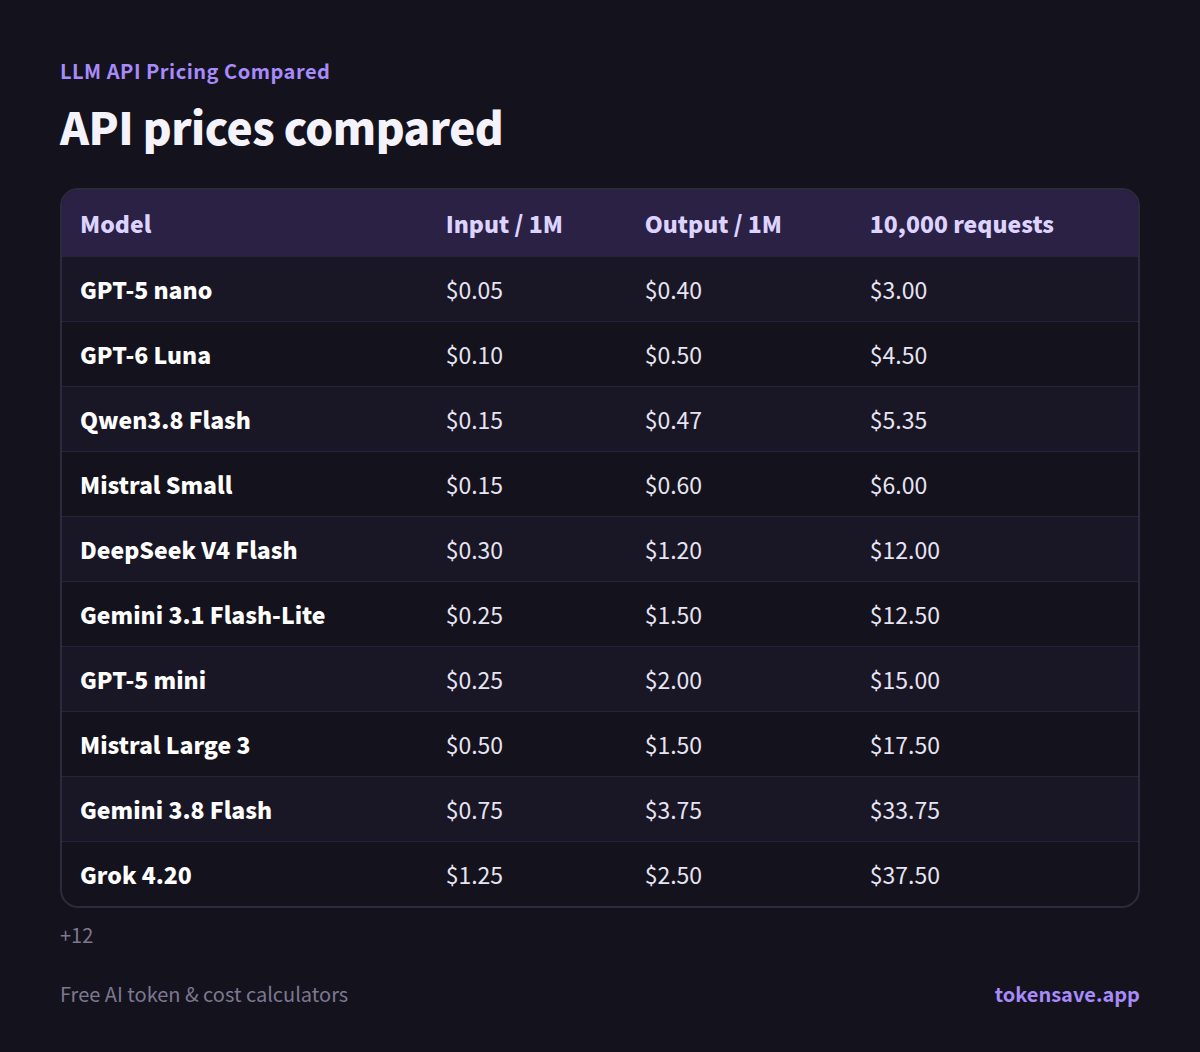
Price per million tokens, sorted from cheapest to most expensive for a typical request (2,000 input tokens and 500 output tokens). The last column is what 10,000 such requests cost.
| Model | Input / 1M | Output / 1M | 10,000 requests |
|---|---|---|---|
| GPT-5 nano | $0.05 | $0.40 | $3.00 |
| GPT-6 Luna | $0.10 | $0.50 | $4.50 |
| Qwen3.8 Flash | $0.15 | $0.47 | $5.35 |
| Mistral Small | $0.15 | $0.60 | $6.00 |
| DeepSeek V4 Flash | $0.30 | $1.20 | $12.00 |
| Gemini 3.1 Flash-Lite | $0.25 | $1.50 | $12.50 |
| GPT-5 mini | $0.25 | $2.00 | $15.00 |
| Mistral Large 3 | $0.50 | $1.50 | $17.50 |
| Gemini 3.8 Flash | $0.75 | $3.75 | $33.75 |
| Grok 4.20 | $1.25 | $2.50 | $37.50 |
| Claude Haiku 4.5 | $1.00 | $5.00 | $45.00 |
| DeepSeek V4 Pro | $1.32 | $3.96 | $46.20 |
| Mistral Medium 3.5 | $1.50 | $7.50 | $67.50 |
| Grok 4.7 | $2.00 | $6.00 | $70.00 |
| Qwen3.8 Max | $2.00 | $6.00 | $70.00 |
| GPT-6 Sol | $2.00 | $10.00 | $90.00 |
| Claude Sonnet 5.5 | $2.00 | $10.00 | $90.00 |
| Gemini 3.1 Pro | $2.00 | $12.00 | $100.00 |
| Kimi K3 | $3.00 | $15.00 | $135.00 |
| Claude Opus 5.5 | $4.00 | $20.00 | $180.00 |
| GPT-6 Astra | $10.00 | $50.00 | $450.00 |
| Claude Fable 5.1 | $10.00 | $50.00 | $450.00 |
List prices in US dollars, checked October 1, 2026. Prices change often, sometimes weekly, so confirm with the provider before a large job. Our token counter uses the same price list and is updated daily.
Three price tiers
Budget (under $0.50 per million input tokens): GPT-5 nano, GPT-6 Luna, Qwen3.8 Flash, Mistral Small, DeepSeek V4 Flash, Gemini 3.1 Flash-Lite, GPT-5 mini. Good for classification, extraction, routing, short answers and anything at high volume.
Mid-range (around $1–3): Gemini 3.8 Flash, Claude Haiku 4.5, DeepSeek V4 Pro, Grok, Mistral Medium, Qwen3.8 Max, GPT-6 Sol, Claude Sonnet 5.5, Gemini 3.1 Pro, Kimi K3. The default for chat assistants, writing, analysis and coding agents.
Flagship ($4 and up): Claude Opus 5.5, GPT-6 Astra, Claude Fable 5.1. Use them where you can show they do better: long, multi-step agent work and hard reasoning.
The price list is not the whole story
Output is the expensive side. On most models, output costs 300–500% more than input. If your app writes long answers, compare output prices first. See Why output tokens cost more.
Tokenizers differ. Each provider splits text into tokens differently. In our test the same English prompt was 38% more tokens on Claude 5.5 than on GPT, and 82% more in Korean, so a lower price per token does not always mean a lower bill. Compare the cost of your own text in the token counter, not just the price list. More in How to count tokens for GPT, Claude and Gemini.
Your language matters. Non-English text uses more tokens: on GPT's tokenizer, about 44% more for Korean, 79% more for Japanese and 100% more for Czech than English.
Discounts change the ranking. Most providers offer cached input at a fraction of the normal price and batch processing at around half price. A mid-range model with good caching can cost less than a budget model without it for apps with long, repeated prompts. See Prompt caching and Batch APIs.
Long prompts can cost more. Some models charge a higher rate above a certain prompt length; GPT-6 models, for example, charge more for requests over 272,000 input tokens.
What is the cheapest LLM API?
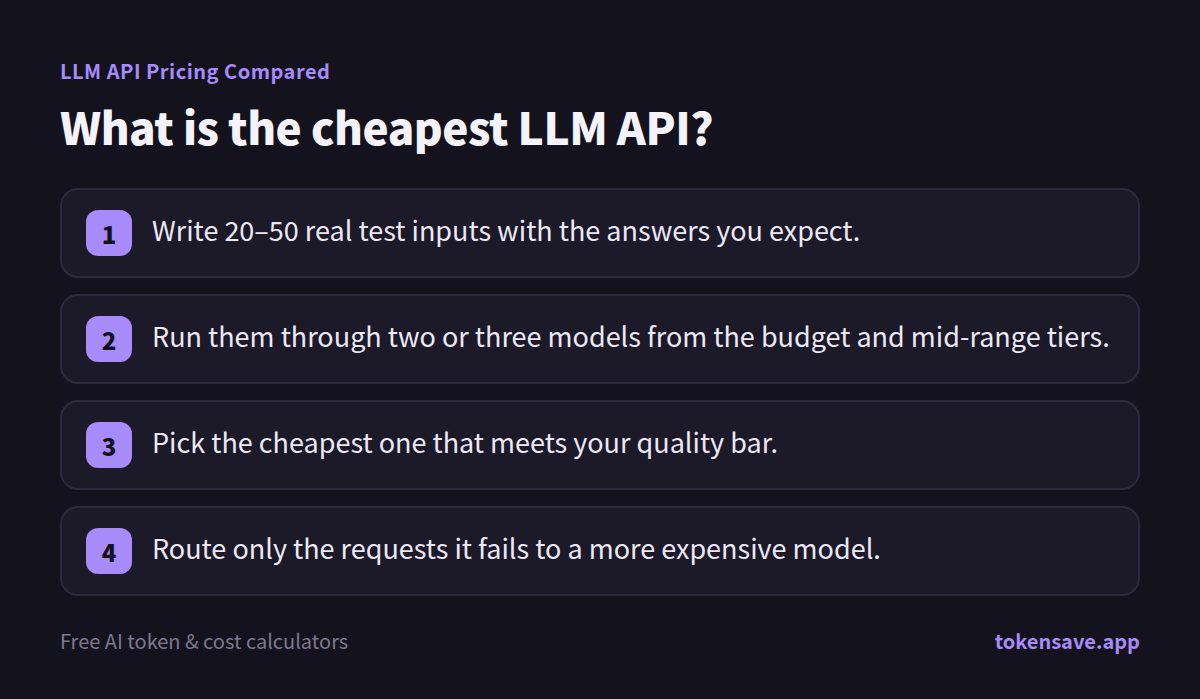
On list price, GPT-5 nano and GPT-6 Luna are the cheapest of the models above, at $0.05 and $0.10 per million input tokens. But the cheapest model that is good enough for your task is what matters. A practical approach:
- Write 20–50 real test inputs with the answers you expect.
- Run them through two or three models from the budget and mid-range tiers.
- Pick the cheapest one that meets your quality bar.
- Route only the requests it fails to a more expensive model.
Estimate your own bill
Paste a real prompt into the token counter to see its cost on every model at once, or read How to estimate your AI API bill for the full method. For subscriptions versus the API, use the Subscription vs API calculator. To put two models side by side, see the model comparison pages.
Sources
- OpenAI API pricing
- OpenAI: GPT-5 nano model
- Claude API pricing
- Gemini API pricing
- xAI API pricing
- DeepSeek API models and pricing
- Mistral AI: Mistral Large 3
- Alibaba Cloud: qwen3.8-flash pricing
- Alibaba Cloud Model Studio pricing
More articles
- Claude Haiku vs Opus for Coding: 330 Measured Runs
- Claude Code Cache Lasts 1 Hour: What a Break Costs (Measured)
- JSON vs YAML vs CSV: Which Data Format Uses the Fewest Tokens?
- How to Estimate Your AI API Bill Before You Build
- How to Count Tokens for GPT, Claude and Gemini (2026)
Paste a prompt to see its tokens and cost on every GPT-6 model, Claude and Gemini.
Open the token counter →