 TokenSave
How to Estimate Your AI API Bill Before You Build
Jonhisking · October 2, 2026
Most surprise AI bills come from one mistake: estimating cost from the price list instead of from real usage. The price per million tokens looks tiny, but the number of tokens a real app sends is usually far larger than people expect. Here is a simple method to estimate your monthly bill before you write any code.
The formula
Every text model is billed the same way:
cost = input tokens × input price + output tokens × output price
Prices are quoted per million tokens, so divide your token counts by 1,000,000. Input tokens are everything you send: the system prompt, the conversation history, any documents, and the user's message. Output tokens are everything the model writes, including hidden reasoning on reasoning models.
Step 1: measure one real request
Write a realistic request: your actual system prompt, a typical user message and a typical answer. Paste each part into the token counter and note:
- Input per request: system prompt + context + user message
- Output per request: a typical answer
Do not guess. A system prompt with instructions and examples is often 1,000–3,000 tokens on its own.
Step 2: multiply by volume
Estimate requests per month. For a chat product, that is users × conversations × messages per conversation.
Step 3: add the multipliers people forget
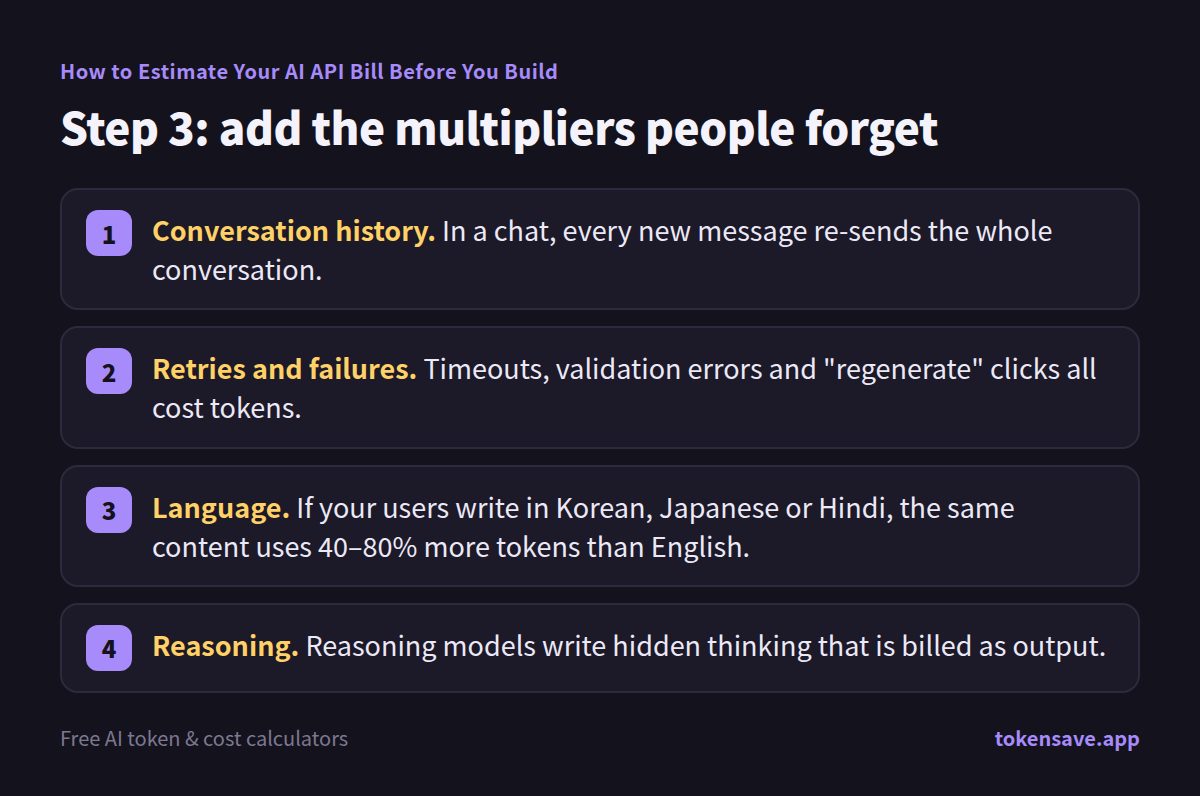
- Conversation history. In a chat, every new message re-sends the whole conversation. Message 10 of a conversation includes messages 1 to 9. Average input per message can be 400–900% larger than a single message.
- Retries and failures. Timeouts, validation errors and "regenerate" clicks all cost tokens. Add 5–15%.
- Language. If your users write in Korean, Japanese or Hindi, the same content uses 40–80% more tokens than English.
- Reasoning. Reasoning models write hidden thinking that is billed as output. It can be much longer than the visible answer.
A worked example
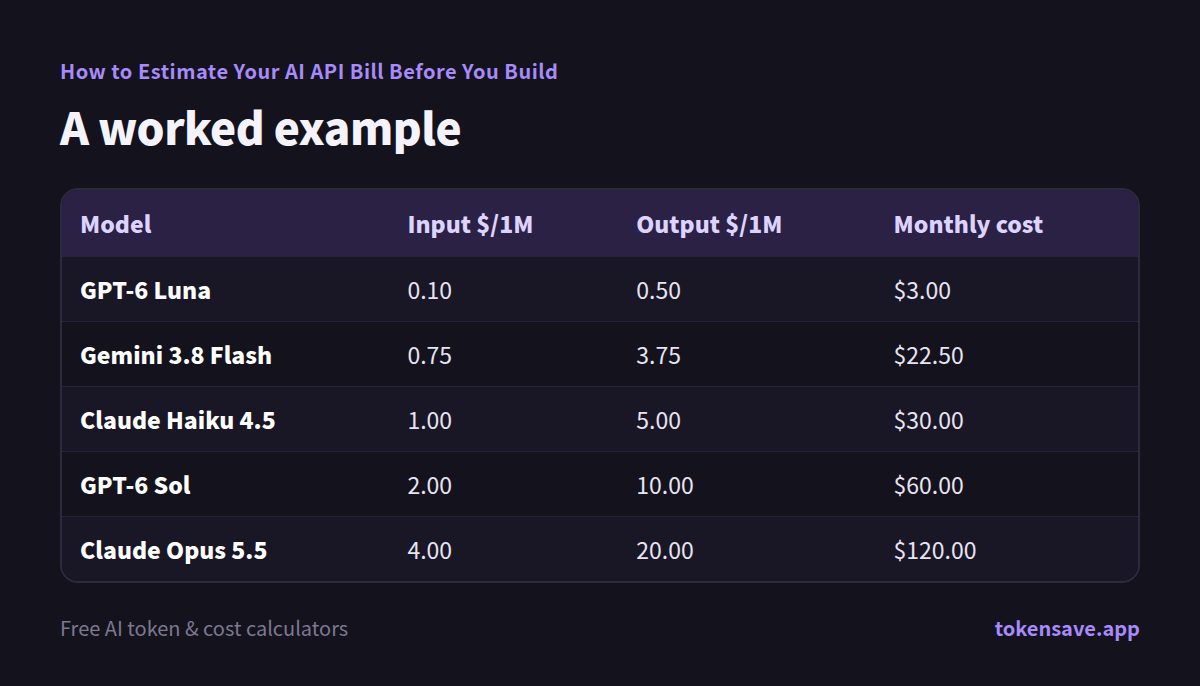
A customer-support bot handles 10,000 conversations a month. Measured per conversation: 1,500 input tokens and 300 output tokens.
That is 15 million input tokens and 3 million output tokens a month. Using API prices checked on October 1, 2026:
| Model | Input $/1M | Output $/1M | Monthly cost |
|---|---|---|---|
| GPT-6 Luna | 0.10 | 0.50 | $3.00 |
| Gemini 3.8 Flash | 0.75 | 3.75 | $22.50 |
| Claude Haiku 4.5 | 1.00 | 5.00 | $30.00 |
| GPT-6 Sol | 2.00 | 10.00 | $60.00 |
| Claude Opus 5.5 | 4.00 | 20.00 | $120.00 |
The same workload ranges from $3 to $120 depending on the model. Now apply the multipliers: if conversations average 6 messages and history is re-sent each time, input could easily grow by 200%, and the GPT-6 Sol bill moves from $60 toward $150.
Ways to bring the number down
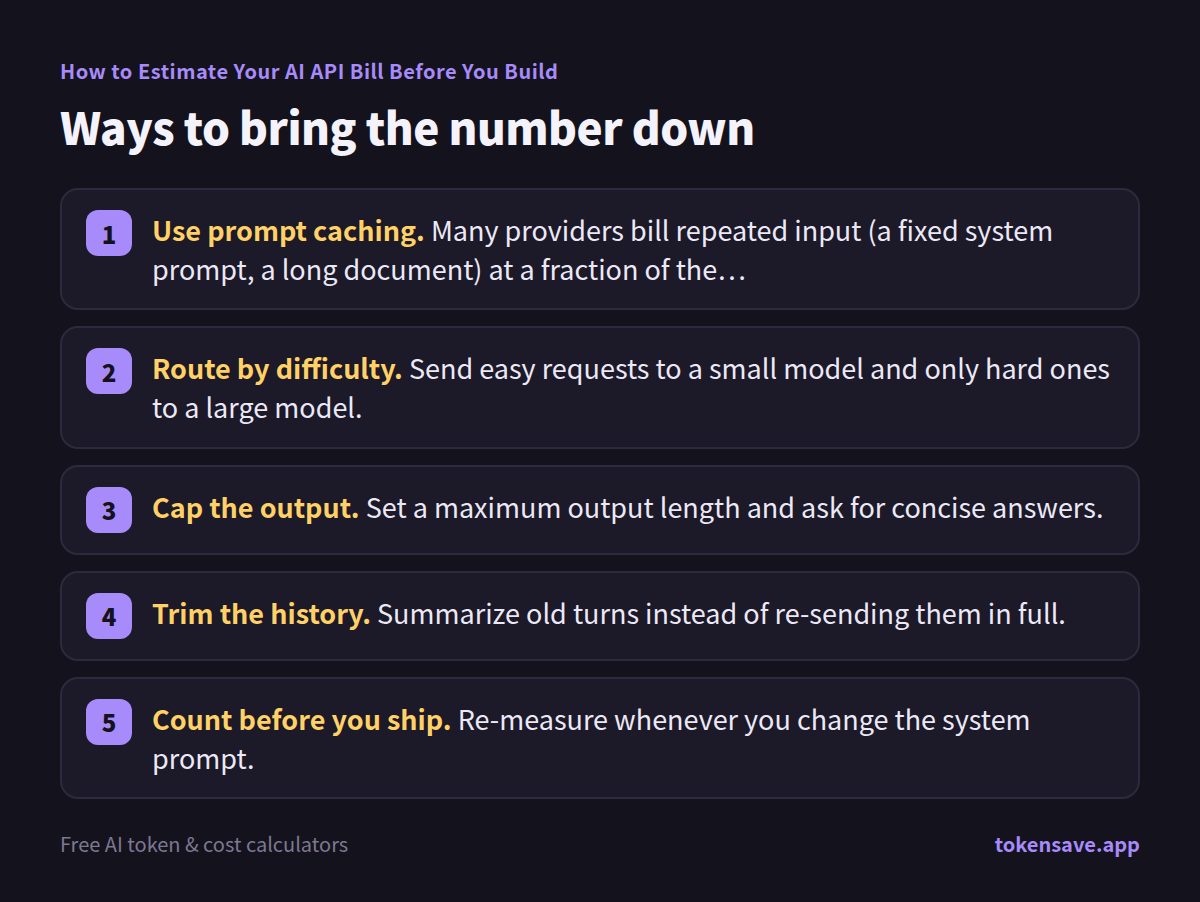
- Use prompt caching. Many providers bill repeated input (a fixed system prompt, a long document) at a fraction of the normal price, often around 10%. Put the fixed part of your prompt first so it can be cached.
- Route by difficulty. Send easy requests to a small model and only hard ones to a large model.
- Cap the output. Set a maximum output length and ask for concise answers.
- Trim the history. Summarize old turns instead of re-sending them in full.
- Count before you ship. Re-measure whenever you change the system prompt.
Check your own numbers
The token counter turns any text into a cost for 30+ models at once, and the Subscription vs API calculator shows whether a monthly plan would be cheaper than paying per token.
Prices change often. Always confirm on the provider's pricing page before a large job.
Sources
- OpenAI API pricing
- GPT-6 Sol model page (OpenAI)
- Gemini Developer API pricing (Google)
- Claude API pricing (Anthropic)
- Reasoning models guide (OpenAI)
- Prompt caching guide (OpenAI)
More articles
- Claude Haiku vs Opus for Coding: 330 Measured Runs
- Claude Code Cache Lasts 1 Hour: What a Break Costs (Measured)
- How to Count Tokens for GPT, Claude and Gemini (2026)
- How Many Tokens Does Code Use? Indentation, Comments and Minification
- How GPT's New Tokenizer Cut Costs in 40 Languages
Measure your real prompt and answer, then see the cost on every model at once.
Open the token counter →