 TokenSave
All comparisons · Scores checked 2026-11-18 · Prices 2026-10-14
AI model capability vs price
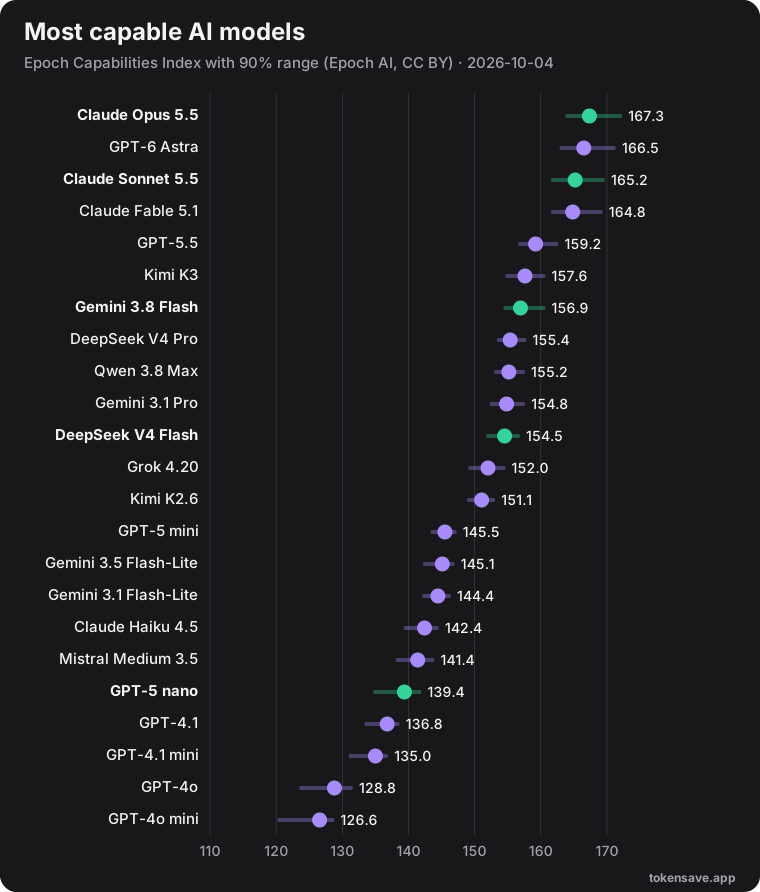
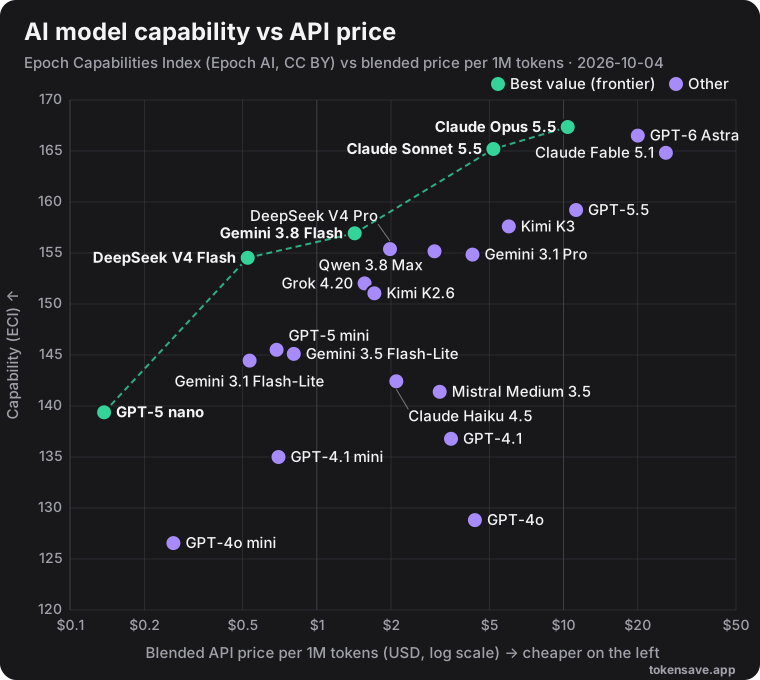
A more expensive model is not always a smarter one. This chart puts each model's general capability, measured by the Epoch Capabilities Index (ECI), against what its API costs. The highest score is Claude Fable 5.2 at 173.5.
The highest score on the Epoch Capabilities Index among the models priced here.
4.8 points below the top model for 50% of its price, and on the best-value frontier.
The cheapest model within 15 points of the top score: 7% of the top model's price.
These models are new, and Epoch AI has not published a capability score for them yet. They join the charts automatically once it does. Their prices today:
- GPT-6.2 Astra$8 / $40 · $16.00
- GPT-6.2 Sol$2 / $10 · $4.00
- Mistral Large 3$0.5 / $1.5 · $0.79
The best-value models
A model is on the best-value frontier when no other model is both cheaper and more capable. From cheapest to most capable: GPT-5 nano, GPT-6 Luna, Gemini 3.8 Flash, GPT-6.1 Terra, GPT-6.1 Sol, Claude Opus 5.5, GPT-6 Astra (legacy), Claude Fable 5.2. Anything below the line costs more than a frontier model with the same or higher score.
All scores and prices
| Model | ECI (90% range) | Input / output per 1M | Blended per 1M |
|---|---|---|---|
| Claude Fable 5.2 ★ best value | 173.5 170–177 | $8 / $40 | $22.08 |
| GPT-6 Astra (legacy) ★ best value | 169.2 166–172 | $10 / $50 | $20.00 |
| Claude Opus 5.5 ★ best value | 168.7 166–172 | $4 / $20 | $11.04 |
| GPT-6.1 Sol ★ best value | 168.6 166–172 | $2 / $10 | $4.00 |
| GPT-6.1 Terra ★ best value | 167.7 165–171 | $1 / $5 | $2.00 |
| Claude Fable 5.1 (legacy) | 167.1 164–170 | $10 / $50 | $27.60 |
| Claude Sonnet 5.5 | 166.6 164–170 | $2 / $10 | $5.52 |
| Gemini 4 Argon | 166.6 164–170 | $2 / $10 | $4.00 |
| GPT-6 Sol | 163.8 161–167 | $2 / $10 | $4.00 |
| GPT-5.5 | 160.2 158–162 | $5 / $30 | $11.25 |
| Gemini 3.8 Flash ★ best value | 158.8 157–161 | $0.75 / $3.75 | $1.50 |
| Kimi K3 | 158.6 157–161 | $3 / $15 | $6.00 |
| Muse Spark 1.3 | 158.2 156–160 | $1.25 / $4.25 | $2.00 |
| Grok 4.7 | 156.4 154–159 | $2 / $6 | $3.00 |
| GPT-6 Luna ★ best value | 156.4 154–158 | $0.1 / $0.5 | $0.20 |
| Gemini 3.1 Pro | 156.2 154–158 | $2 / $12 | $4.50 |
| Qwen 3.8 Max | 156.0 154–158 | $2 / $6 | $3.00 |
| DeepSeek V4 Pro | 156.0 154–158 | $1.32 / $3.96 | $1.98 |
| DeepSeek V4.1 Flash | 154.4 153–156 | $0.3 / $1.2 | $0.52 |
| Grok 4.20 | 152.3 151–154 | $1.25 / $2.5 | $1.56 |
| Kimi K2.6 | 151.6 150–153 | $0.95 / $4 | $1.71 |
| GPT-5 mini | 146.0 144–148 | $0.25 / $2 | $0.69 |
| Gemini 3.5 Flash-Lite | 145.7 144–147 | $0.3 / $2.5 | $0.85 |
| Gemini 3.1 Flash-Lite | 145.0 143–147 | $0.25 / $1.5 | $0.56 |
| Claude Haiku 4.5 | 142.8 141–144 | $1 / $5 | $2.06 |
| Mistral Medium 3.5 | 141.6 138–145 | $1.5 / $7.5 | $3.15 |
| GPT-5 nano ★ best value | 139.1 137–141 | $0.05 / $0.4 | $0.14 |
| GPT-4.1 | 136.2 134–138 | $2 / $8 | $3.50 |
| GPT-4.1 mini | 134.3 132–136 | $0.4 / $1.6 | $0.70 |
| GPT-4o | 128.8 126–131 | $2.5 / $10 | $4.38 |
| GPT-4o mini | 123.8 120–127 | $0.15 / $0.6 | $0.26 |
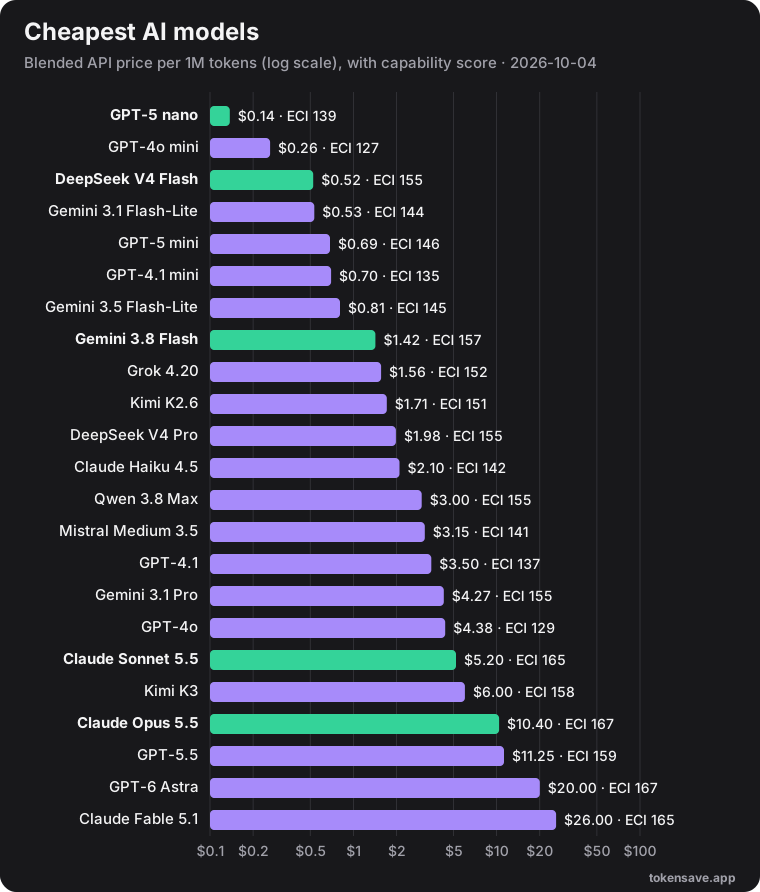
Blended price = (3 × input + output) ÷ 4 per million tokens, a typical chat mix, adjusted for each model's tokenizer (how many tokens it uses for the same English text). Standard list prices, no caching or batch discounts.
What the score means
ECI combines dozens of benchmarks (math, coding, science, reasoning and more) into one scale, so models tested on different benchmarks can still be compared. A gap of a few points is often within the margin of error; the 90% range in the table shows how sure the estimate is. It measures general capability, not your task: for a specific job, test a few frontier models on your own prompts.
To see what your own prompts cost on each model, paste them into the token counter, or compare two models side by side on the comparison pages.
What the chart means, model by model: Best value LLM in October 2026.
Capability scores: Epoch Capabilities Index by Epoch AI, used under CC BY 4.0. Prices: TokenSave, updated daily.