 TokenSave
 Data · Dataset
Where AI coding agents first fail: Haiku, Sonnet, Opus, Codex and Gemini on six levels of coding tasks
Given a clear spec, almost every run built the apps: Claude Haiku 5.5 got full marks on all 21 runs from a five-level game up to a spreadsheet engine with cycle detection. The first failures came from a real bug in a real project: on the hardest of three bugs fixed in the marked Markdown parser in September and October 2026, no tool passed the upstream test, in any run. Haiku, Sonnet and Opus scored the same number of full-mark runs; Haiku cost about 94% less per run than Opus at API prices.
Measured 2026-10-23 to 2026-10-24 · 136 runs (+6 excluded) · Claude Code 2.1.295, Codex CLI 0.162, Antigravity CLI 1.4.5 · License CC BY 4.0
DOI 10.5281/zenodo.23600477 · Also on Hugging Face · Kaggle · GitHub
Estimate your own Claude Code or Codex bill → See the monthly cost of Claude Code and Codex for your usage: API per task vs Claude and ChatGPT plans. Free, no sign-up.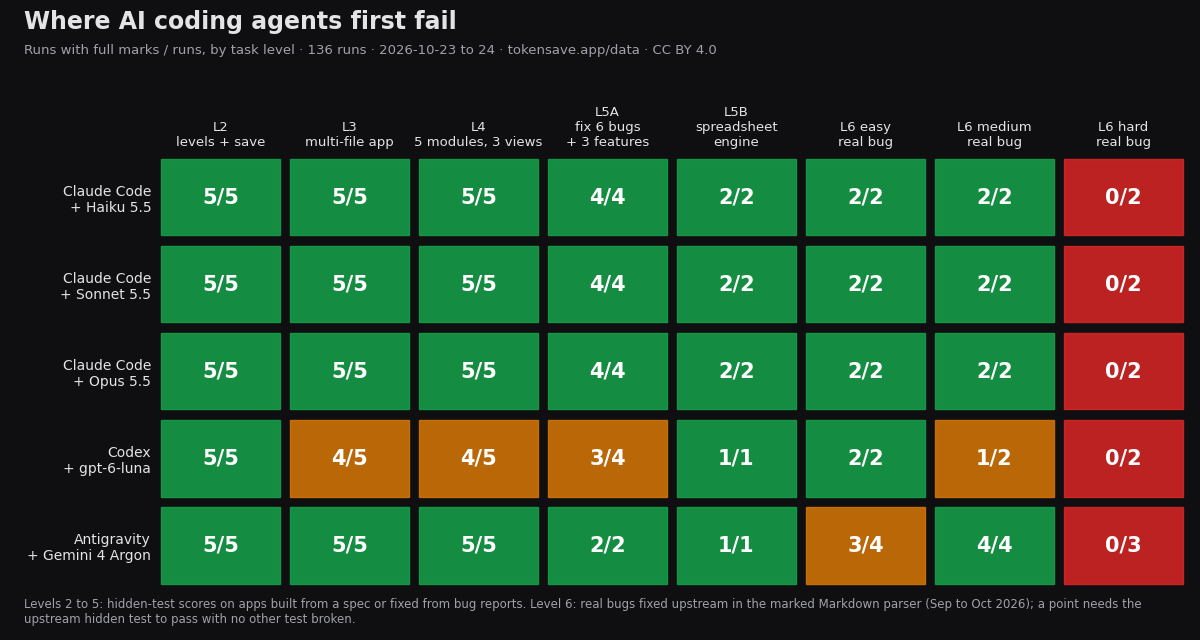
Key findings
- Levels 2 to 5 (apps from a spec, or an existing app to fix): Haiku, Sonnet and Opus 21/21 runs with full marks each, Antigravity + Gemini 4 Argon 18/18, Codex 17/20 (one syntax error from literal \n in a file, one app whose fixed category list and −$ amounts failed three checks, one missed report row).
- Level 5A was a brownfield task: a 1,032-line budget app with six planted bugs described only by symptoms, plus three features. Every Claude run fixed all six bugs, added all three features and kept all 23 earlier tests passing.
- Level 6, real bugs in marked: the easy one (a one-line regular expression) and the medium one were solved by almost every run, Haiku and Sonnet in 15 to 20 seconds. On the hard one (a backslash at the end of a code span hiding later emphasis), Opus and Sonnet passed 6 of the 7 cases in the upstream test, Haiku 5 (and broke 15 other spec tests in one run), Codex and Gemini 3 (the unfixed code also passes 3). All of them fixed the examples in the bug report and missed cases it did not mention.
- Cost per run at API prices (Claude Code’s own figure): Haiku $0.027, Sonnet $0.20, Opus $0.44 on average. Codex and Antigravity ran on subscription plans and report no price.
- Antigravity’s headless mode ends a turn at the first denied command. With read-only allow-rules, several Gemini runs stopped before editing (a
node -eline with quotes needs an exact rule on Windows). With full permissions Gemini solved the easy and medium bugs too, but took 2 to 11 minutes, and one hard run used its whole 30-minute limit without an edit.
Runs with full marks
Full marks = every hidden check passed. Level 6: the upstream fix’s test passes and no other marked spec test newly fails. Gemini level 6 cells mix allow-rule runs and full-permission re-runs; excluded runs (stopped by the harness or by quota) are in the CSV with a note.
| Tool + model | L2 levels + save | L3 multi-file app | L4 5 modules, 3 views | L5A fix 6 bugs + 3 features | L5B spreadsheet engine | L6 easy real bug | L6 medium real bug | L6 hard real bug |
|---|---|---|---|---|---|---|---|---|
| Claude Code + Haiku 5.5 | 5/5 | 5/5 | 5/5 | 4/4 | 2/2 | 2/2 | 2/2 | 0/2 |
| Claude Code + Sonnet 5.5 | 5/5 | 5/5 | 5/5 | 4/4 | 2/2 | 2/2 | 2/2 | 0/2 |
| Claude Code + Opus 5.5 | 5/5 | 5/5 | 5/5 | 4/4 | 2/2 | 2/2 | 2/2 | 0/2 |
| Codex + gpt-6-luna | 5/5 | 4/5 | 4/5 | 3/4 | 1/1 | 2/2 | 1/2 | 0/2 |
| Antigravity + Gemini 4 Argon | 5/5 | 5/5 | 5/5 | 2/2 | 1/1 | 3/4 | 4/4 | 0/3 |
Average seconds per run
| Tool + model | L2 levels + save | L3 multi-file app | L4 5 modules, 3 views | L5A fix 6 bugs + 3 features | L5B spreadsheet engine | L6 easy real bug | L6 medium real bug | L6 hard real bug |
|---|---|---|---|---|---|---|---|---|
| Claude Code + Haiku 5.5 | 91 | 86 | 163 | 136 | 333 | 18 | 17 | 41 |
| Claude Code + Sonnet 5.5 | 33 | 38 | 107 | 88 | 141 | 18 | 16 | 38 |
| Claude Code + Opus 5.5 | 57 | 87 | 128 | 94 | 233 | 29 | 28 | 86 |
| Codex + gpt-6-luna | 45 | 92 | 125 | 75 | 147 | 32 | 44 | 36 |
| Antigravity + Gemini 4 Argon | 111 | 110 | 237 | 235 | 295 | 447 | 266 | 1,198 |
Average API cost per run (Claude Code)
| Tool + model | L2 levels + save | L3 multi-file app | L4 5 modules, 3 views | L5A fix 6 bugs + 3 features | L5B spreadsheet engine | L6 easy real bug | L6 medium real bug | L6 hard real bug |
|---|---|---|---|---|---|---|---|---|
| Claude Code + Haiku 5.5 | $0.018 | $0.019 | $0.037 | $0.032 | $0.096 | $0.005 | $0.005 | $0.011 |
| Claude Code + Sonnet 5.5 | $0.12 | $0.13 | $0.28 | $0.34 | $0.38 | $0.081 | $0.072 | $0.12 |
| Claude Code + Opus 5.5 | $0.28 | $0.40 | $0.59 | $0.57 | $0.92 | $0.20 | $0.18 | $0.39 |
The tasks
- L2: a five-level brick game with pause, a level-skip key and saved level and best score (9 checks, played in headless Chromium).
- L3: a multi-file expense tracker with CSV and summary modules (12 checks).
- L4: a budget app with five modules (CSV with line breaks, ranges, monthly repeats with month ends, budgets, 50-step undo) and three hash-routed views (23 checks).
- L5A: the L4 app written by one of the Gemini runs (8 files, 1,032 lines) with six planted bugs reported only as user symptoms, plus three new features (38 checks, including the 23 L4 tests as regression tests). Because Gemini wrote the starting code, it may have had a small advantage.
- L5B: a spreadsheet engine and page: precedence with unary minus and right-associative ^, eight functions, six error values, cycle detection and recovery, relative and $absolute copy, undo, CSV (38 checks, 32 of them calling the engine directly).
- L6: three bugs fixed in marked in September and October 2026 (commits 123ce04b, cc07bb9c and 6a57018f). Each run started from the commit before the fix with a symptom-only bug report; we copied back only its src/ folder, then ran the upstream fix’s spec file and marked’s full spec suite (about 1,900 checks).
Method
- One Windows 11 laptop, each run in a fresh folder. Claude Code 2.1.295 (
-p, effort medium, acceptEdits), Codex CLI 0.162 (exec, medium, workspace-write sandbox), Antigravity CLI 1.4.5 (-p, gemini-4-argon-medium, accept-edits with read-only allow-rules; full permissions for the level 6 re-run). - Every checker was validated before the runs: a reference solution scores full marks and deliberately broken versions lose exactly their target checks. Runs were scored twice where a check depends on timing.
- We stopped L5A after 4 rounds and L5B after 2 because every run scored full marks; L6 has 2 runs per tool and task.
Limitations
- Few runs per cell at the higher levels (1 to 5). The level 6 result rests on three bugs from one project.
- The prompts list every element id and function name the tests use, which makes levels 2 to 5 easier than real work.
- The tools differ in more than the model: Codex can run commands in its sandbox, Claude Code in acceptEdits cannot run shell commands, Antigravity stops on a denied command.
- The agents could not install packages, so none of them could run marked’s tests while fixing it.
How to cite
Free to use, quote and republish with attribution under CC BY 4.0. Please link to this page.
TokenSave (2026). Where AI coding agents first fail: Haiku, Sonnet, Opus, Codex and Gemini on six levels of coding tasks [Data set]. Zenodo. https://doi.org/10.5281/zenodo.23600477
BibTeX
@misc{tokensave_ai_coding_limit_line_2026,
  author    = {{TokenSave}},
  title     = {Where AI coding agents first fail: Haiku, Sonnet, Opus, Codex and Gemini on six levels of coding tasks},
  year      = {2026},
  publisher = {Zenodo},
  doi       = {10.5281/zenodo.23600477},
  url       = {https://doi.org/10.5281/zenodo.23600477},
  note      = {Dataset, CC BY 4.0}
}
Embed the chart
Related
- Vibe coding by Claude model
- Claude effort levels: tokens, time and cost
- Antigravity CLI vs Claude Code vs Codex
- Estimate your own Claude Code or Codex bill
Questions or corrections: contact@jonhisking.com