 TokenSave
 Data · Dataset
Antigravity CLI vs Claude Code vs Codex: the same Opus 5.5 read 68% to 88% fewer tokens in Antigravity
The same model, Claude Opus 5.5, read 68% to 88% fewer input tokens in Google’s Antigravity CLI than in Claude Code for the same coding task, and 71% to 85% fewer before doing anything. Both made a working game. Gemini 4 Argon in Antigravity also stayed far below Claude Code and Codex. The range comes from one open question: whether Antigravity’s separately reported cache reads should be added on top.
Measured 2026-10-22 · 44 runs · Claude Code 2.1.295, Codex CLI 0.162, Antigravity CLI 1.4.5 · License CC BY 4.0 · Earlier: Claude Code vs Codex
DOI 10.5281/zenodo.23569397 · Also on Hugging Face · GitHub
Estimate your own Claude Code or Codex bill → See the monthly cost of Claude Code and Codex for your usage: API per task vs Claude and ChatGPT plans. Free, no sign-up.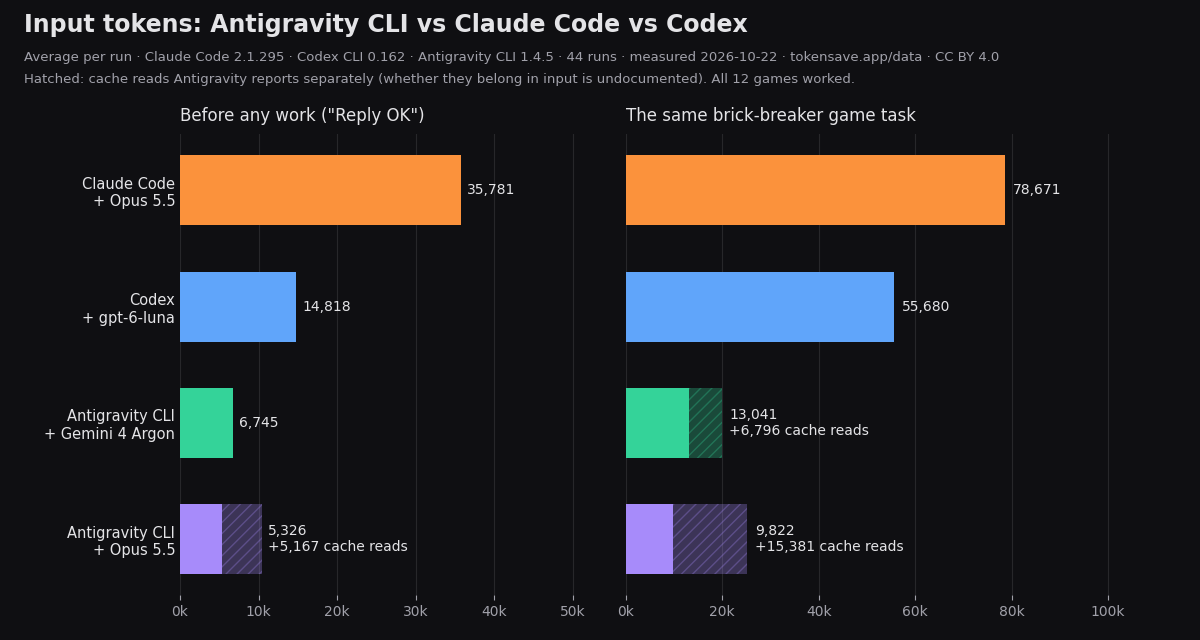
Key findings
- Startup: 35,781 input tokens in Claude Code, 14,818 in Codex, 6,745 in Antigravity with Gemini 4 Argon and 5,326 in Antigravity with Opus 5.5 (10,493 counting its cache reads), for the prompt “Reply with the single word OK.” with no MCP server. Most of it is each tool’s own instructions and tool definitions, sent with every request.
- Same task, same model: asked to build a brick-breaker game, Opus 5.5 read 78,671 input tokens in Claude Code and 9,822 in Antigravity (25,203 counting cache reads), wrote 7,313 and 4,378 output tokens, and took 58 and 42 seconds. Claude Code’s games were longer (451 lines on average against 236). Claude Code put the run at $0.37 at API prices; Antigravity shows no price.
- Gemini 4 Argon in Antigravity read 13,041 input tokens (19,837 counting cache reads) and wrote the longest games (608 lines), but took the longest too (81 seconds). Codex read 55,680 on average (47,975 to 70,704) and wrote minified games of about 42 lines.
- MCP tools barely matter any more. Thirty test tools added 388 tokens in Claude Code, none in Codex (14,618 in seven of its eight startup runs, with or without tools), 582 in Antigravity with Gemini and 417 with Opus. In Antigravity one tool already added 456 (Gemini) and 278 (Opus) and 29 more added little, so all four now seem to load a tool’s details only when it is used.
- All 12 games worked in a headless-browser check: the score rises when bricks break, level 2 appears, and lives go 3, 2, 1, 0. The automatic check could not read the score in two Codex games; a manual check showed bricks breaking and points adding up in both.
- Why Antigravity: Google stopped serving Gemini CLI to personal accounts (Google AI Pro, Ultra and free Code Assist) on 2026-06-18 and pointed them to Antigravity CLI. Antigravity can also run Claude models, which is what makes the same-model comparison possible.
Startup tokens and MCP tools
Input tokens for “Reply with the single word OK.”, average of two runs. In brackets: Antigravity’s separately reported cache reads, and the change against no MCP server.
| MCP tools | Claude Code + Opus 5.5 | Codex + gpt-6-luna | Antigravity + Gemini 4 Argon | Antigravity + Opus 5.5 |
|---|---|---|---|---|
| 0 | 35,781 | 14,818 | 6,745 | 5,326 (+5,167 cache) |
| 1 | 35,794 (+13) | 14,618 (−200) | 7,202 (+456) | 5,604 (+5,583 cache) (+278) |
| 10 | 35,917 (+136) | 14,618 (−200) | 7,242 (+497) | 5,662 (+5,583 cache) (+336) |
| 30 | 36,169 (+388) | 14,618 (−200) | 7,328 (+582) | 5,743 (+5,583 cache) (+417) |
The same coding task
“Make a brick-breaker game that runs in the browser as a single file named index.html … 2 levels, a score display and 3 lives … keyboard and mouse.” Average of three runs each, medium effort.
| Tool | Input tokens | Cache reads reported separately | Output tokens | Seconds | Lines | Games working |
|---|---|---|---|---|---|---|
| Claude Code + Opus 5.5 | 78,671 | included | 7,313 | 58 | 451 | 3 of 3 |
| Codex + gpt-6-luna | 55,680 | included | 4,563 | 68 | 42 | 3 of 3 |
| Antigravity + Gemini 4 Argon | 13,041 | 6,796 | 6,373 | 81 | 608 | 3 of 3 |
| Antigravity + Opus 5.5 | 9,822 | 15,381 | 4,378 | 42 | 236 | 3 of 3 |
How to read Antigravity’s numbers
agy --output-format json reports input_tokens, output_tokens, thinking_tokens, cache_read_tokens and total_tokens, where total is input plus output. Its documentation does not say whether cache reads are part of input. In our Opus runs the cache reads (15,381 on the game task) were larger than the reported input (9,822), so there they cannot be contained in it. We therefore show both: the reported input as the low figure and input plus cache reads as the high one. Even the high figure is far below Claude Code’s.
Method
- Windows 11, 2026-10-22. Every run in its own empty folder, one after another, with no other MCP servers.
- Claude Code 2.1.295, Opus 5.5, Max plan:
claude -p --output-format json --mcp-config mcp.json --strict-mcp-config; the game at--effort medium --permission-mode acceptEdits. Input = input + cache creation + cache read. - Codex CLI 0.162.0-alpha.17.2, gpt-6-luna, ChatGPT plan:
codex exec --json, reasoning effort low for startup and medium for the game, MCP server added with-c mcp_servers.…. Input includes cached input. - Antigravity CLI 1.4.5 (
agy), personal Google account:agy -p --output-format json --model gemini-4-argon-mediumorclaude-opus-5-5-medium; the game with--mode accept-edits. The MCP server was written to the global~/.gemini/config/mcp_config.jsonfor each startup run and removed afterwards. - MCP test server: the same small stdio server as in our Claude Code vs Codex dataset, exposing 1, 10 or 30 tracker tools with a one-sentence description and a five-field schema each.
- Games were checked in headless Chromium: break bricks and watch the score, clear or skip to level 2, and lose the ball until lives reach zero. Scripts and every log are in the GitHub mirror.
Limitations
- Two runs per startup test and three per game. One task, one machine, one day.
- Token counts are each tool’s own report, and the three tools count cache differently (see above). Prices are not compared: Codex and Antigravity show none on a subscription.
- We cannot see how Antigravity sets up Opus 5.5 behind its
claude-opus-5-5-mediumname, so its settings may differ from Claude Code’s medium effort.
How to cite
Free to use, quote and republish with attribution under CC BY 4.0. Please link to this page.
TokenSave (2026). Antigravity CLI vs Claude Code vs Codex: startup tokens, MCP tools and the same coding task [Data set]. Zenodo. https://doi.org/10.5281/zenodo.23569397
Embed the chart
Related
- Claude Code vs Codex: startup tokens and MCP tools
- What the Claude Code harness costs
- Claude Code baseline tokens by version
- Estimate your Claude Code or Codex bill
Questions or corrections: contact@jonhisking.com