 TokenSave
What Is a Token? A Plain-English Guide for AI Users
Jonhisking · October 2, 2026
If you use ChatGPT, Claude or Gemini through an app, you rarely see the word "token". The moment you look at an API price list, it is everywhere: $2 per million input tokens, a 1 million token context window, max output 32K tokens. This guide explains what a token is, how to estimate how many your text uses, and why it matters for both cost and quality.
A token is a piece of text, not a word
AI language models do not read letters or words. Before your text reaches the model, a tokenizer cuts it into pieces from a fixed vocabulary of roughly 100,000 to 200,000 entries. Common words are usually one piece. Rare words, names and code get split into several.
For example, the sentence below has 10 words and 11 tokens on GPT's current tokenizer (o200k): one per word, plus one for the full stop.
Please summarize the customer email below in three bullet points.
Every word here is common enough to be a single token, including the space in front of it. A product code is different: XJ-4471B is only 8 characters but splits into 6 tokens (X, J, -, 447, 1, B).
Rules of thumb for English
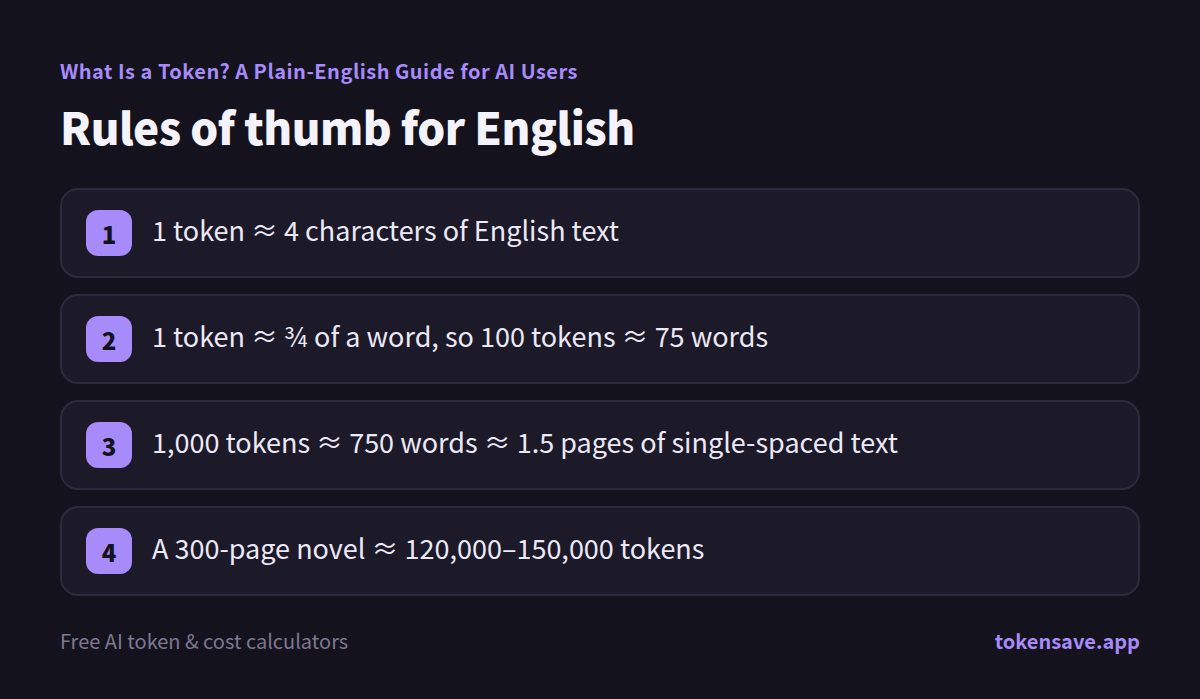
- 1 token ≈ 4 characters of English text
- 1 token ≈ ¾ of a word, so 100 tokens ≈ 75 words
- 1,000 tokens ≈ 750 words ≈ 1.5 pages of single-spaced text
- A 300-page novel ≈ 120,000–150,000 tokens
These are averages. Technical text, code, URLs and numbers use more tokens per character than plain prose. On current GPT models, everyday English is actually a little cheaper than this rule: we measured about 1.1–1.15 tokens per word. See Tokens per word, measured, or convert any word count with the tokens to words converter.
Other languages use more tokens
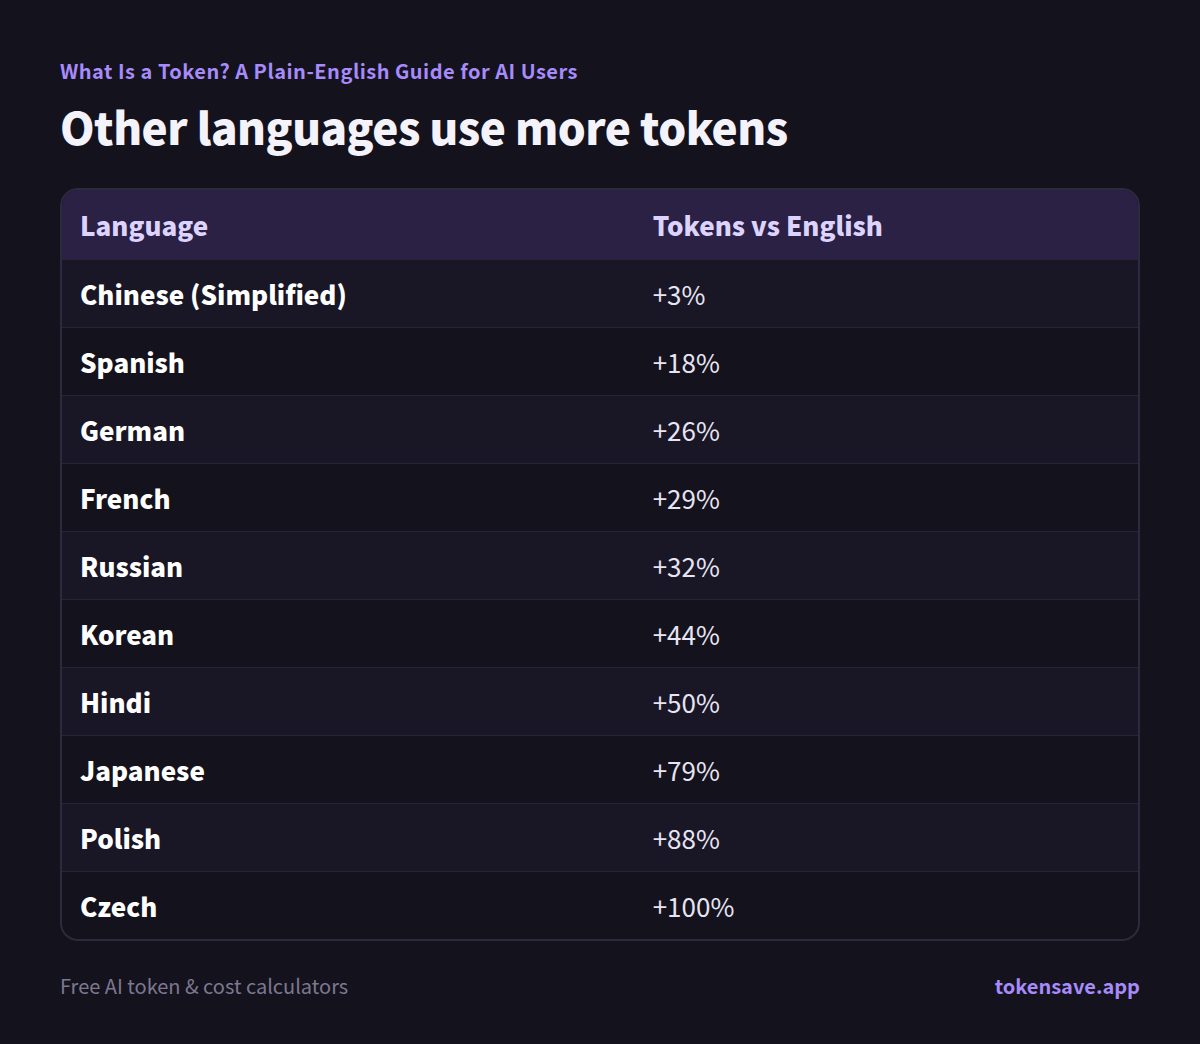
Tokenizers are trained mostly on English, so the same meaning written in another language usually takes more tokens. We measured the same prompt in 41 languages on GPT's o200k tokenizer:
| Language | Tokens vs English |
|---|---|
| Chinese (Simplified) | +3% |
| Spanish | +18% |
| German | +26% |
| French | +29% |
| Russian | +32% |
| Korean | +44% |
| Hindi | +50% |
| Japanese | +79% |
| Polish | +88% |
| Czech | +100% |
Because API pricing is per token, a Japanese prompt costs about 80% more than the same prompt in English. The full 41-language study has every language and how it was measured.
Different models count differently
Each model family has its own tokenizer. OpenAI, Anthropic and Google all use different vocabularies, so the same text comes out at a different count. In our test the same English prompt was 38% more tokens on Claude 5.5 than on GPT, while Gemini was about the same as GPT. When you compare prices between providers, compare the cost of your actual text, not just the price per million tokens.
Why tokens matter
Cost. API prices are quoted per million tokens, with separate prices for input (what you send) and output (what the model writes back). Output is usually 300–500% more expensive than input.
Limits. Every model has a context window: the maximum number of tokens it can consider at once, including the whole conversation so far. Plans and APIs also cap how many tokens you can use per minute or per day.
Quality. Very long inputs can make answers worse, because models pay less attention to the middle of a long context. Fewer, better-chosen tokens often give a sharper answer. See Context windows explained.
How to count tokens exactly
Paste your text into the TokenSave token counter. It runs the real tokenizer in your browser for GPT models, shows an estimate for Claude and Gemini, and converts the count into a price for each model. Nothing you type leaves your device.
Key takeaways
- A token is a chunk of text from the model's vocabulary, about 4 English characters.
- You pay per token, and output tokens cost more than input tokens.
- Non-English text, code and numbers use more tokens for the same meaning.
- Count your real text before you estimate a budget.
Sources
- What are tokens and how to count them (OpenAI Help Center)
- tiktoken (OpenAI tokenizer, o200k_base)
- tiktoken model-to-encoding map
More articles
- Claude Haiku vs Opus for Coding: 330 Measured Runs
- Claude Code Cache Lasts 1 Hour: What a Break Costs (Measured)
- 15 Useful AI Websites Worth Bookmarking (Free to Start)
- Tokens per Word, Measured: English and 11 Other Languages
- Same prompt, 41 languages: GPT token cost compared
Paste any text to see its exact token count and cost on 30+ models.
Open the token counter →