 TokenSave
RAG vs Long Context: What It Costs to Ask Questions About Big Documents
Jonhisking · October 2, 2026
Models with million-token context windows can read an entire manual, codebase or contract in one go. So why do so many apps still use retrieval-augmented generation (RAG), searching for a few relevant passages and sending only those? The answer is mostly cost. Here is the maths, and when each approach makes sense.
The two approaches
Long context: put the whole document in the prompt with every question. Simple to build: no search, no chunking, no index.
RAG: split the document into small chunks, index them, and for each question retrieve the handful of chunks most likely to contain the answer. Only those go into the prompt.
The cost per question
Take a 500-page product manual. At roughly 500 words per page, that is about 250,000 words, or around 330,000 tokens. It fits comfortably in the context window of current flagship models.
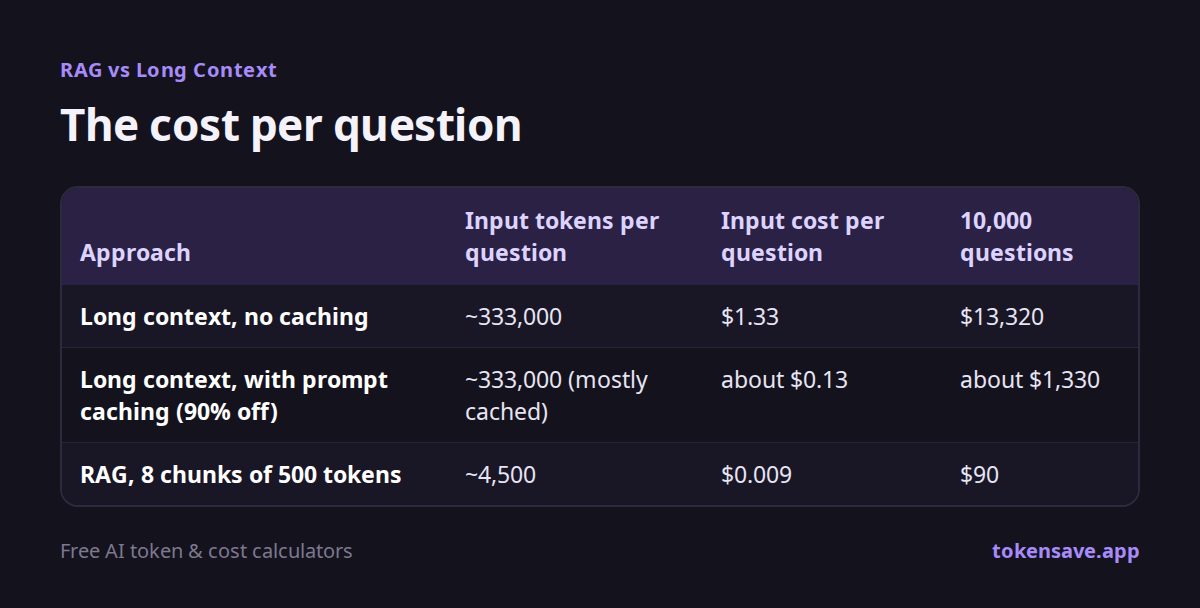
Now answer questions about it on GPT-6 Sol, at $2 per million input tokens and $0.20 cached (checked October 9, 2026). OpenAI bills any prompt over 272,000 input tokens at double the input and cache rates for the whole request, so each long-context question here pays $4 per million input tokens ($0.40 cached), and its output costs 50% more too. We compare input only, so the real gap is slightly larger than shown.
| Approach | Input tokens per question | Input cost per question | 10,000 questions |
|---|---|---|---|
| Long context, no caching | ~333,000 | $1.33 | $13,320 |
| Long context, with prompt caching (90% off) | ~333,000 (mostly cached) | about $0.13 | about $1,330 |
| RAG, 8 chunks of 500 tokens | ~4,500 | $0.009 | $90 |
Even with caching, sending the whole manual costs around 1,400% more than RAG. Without caching, it is $1.33 per question against $0.009 for RAG.
It is not only about money
Speed. Reading 330,000 tokens takes time. A long-context request can take many seconds before the first word appears, while a RAG request with 4,500 tokens starts almost immediately.
Accuracy. Long context is not automatically more accurate. Models tend to use information at the beginning and end of a long input better than information in the middle. A focused prompt with the right three passages often gets a sharper answer than the entire manual. See Context windows explained.
But retrieval can miss. RAG only works if the search finds the right chunks. If the answer depends on information spread across many sections, or the question is worded very differently from the text, retrieval may bring back the wrong passages, and the model cannot answer what it never sees.
When long context is the better choice
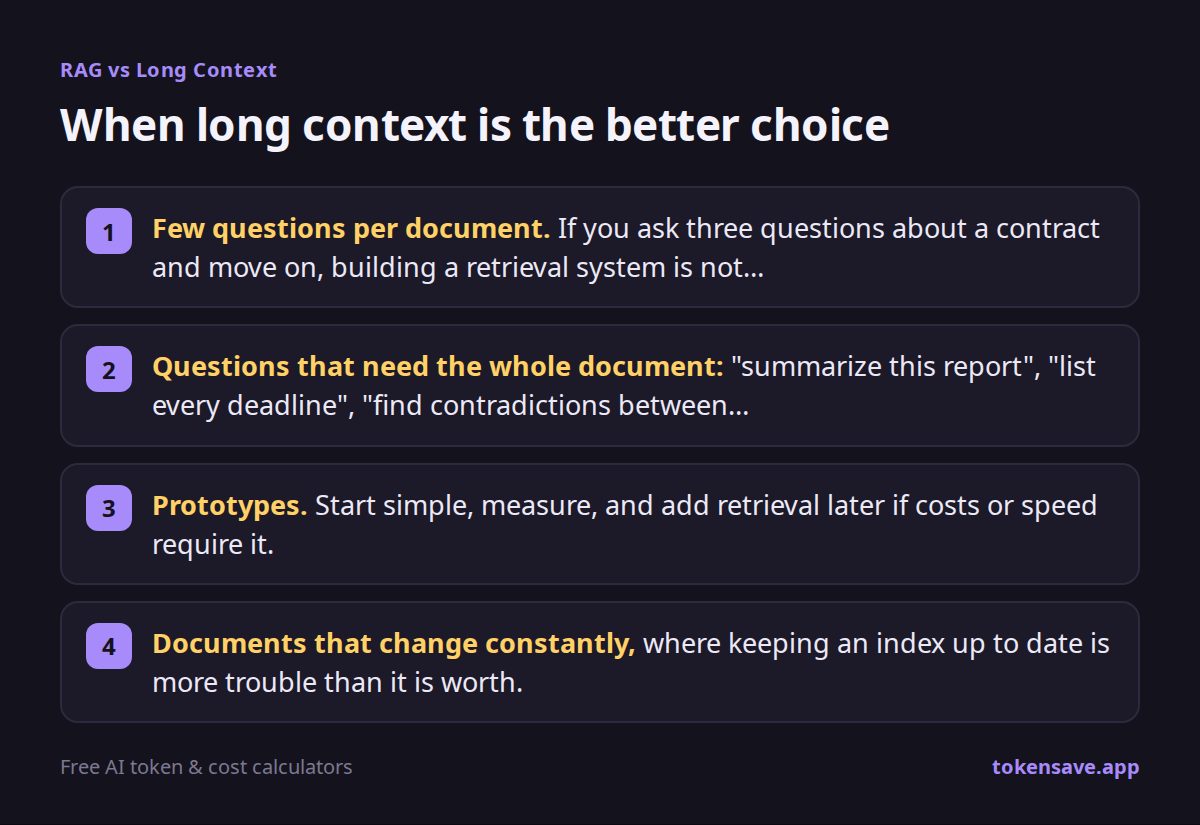
- Few questions per document. If you ask three questions about a contract and move on, building a retrieval system is not worth it.
- Questions that need the whole document: "summarize this report", "list every deadline", "find contradictions between sections".
- Prototypes. Start simple, measure, and add retrieval later if costs or speed require it.
- Documents that change constantly, where keeping an index up to date is more trouble than it is worth.
When RAG is the better choice
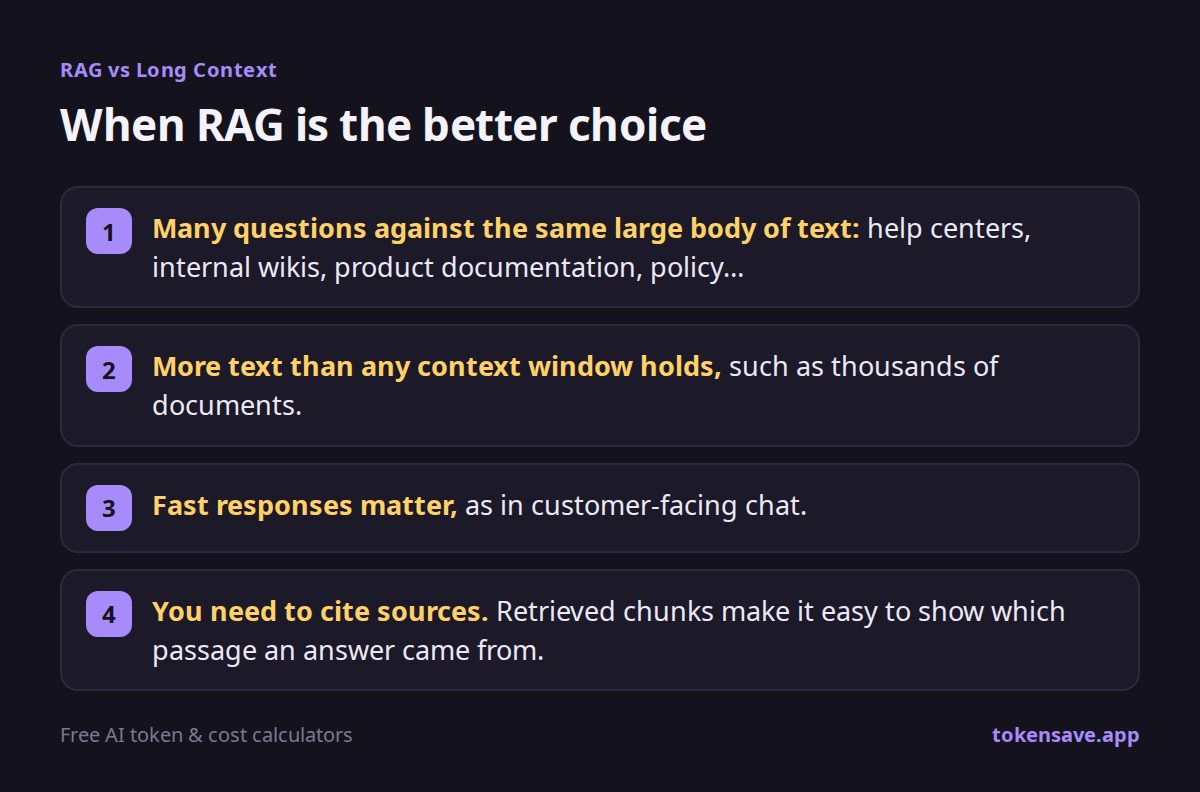
- Many questions against the same large body of text: help centers, internal wikis, product documentation, policy libraries.
- More text than any context window holds, such as thousands of documents.
- Fast responses matter, as in customer-facing chat.
- You need to cite sources. Retrieved chunks make it easy to show which passage an answer came from.
The common middle ground
Many production systems combine both: retrieve generously (say, 20–50 chunks instead of 5), use a model with a large context window, and rely on prompt caching for any instructions that repeat. This keeps costs low while making it much less likely that the right passage is missed.
Estimate your case
Paste a sample of your document into the token counter to see how many tokens it uses and what one question would cost on each model. Then multiply by your expected number of questions per month.
Sources
- GPT-6 Sol model page (OpenAI)
- Prompt caching guide (OpenAI)
- Liu et al., Lost in the Middle (arXiv, 2023)
More articles
- Claude Haiku vs Opus for Coding: 330 Measured Runs
- Claude Code Cache Lasts 1 Hour: What a Break Costs (Measured)
- Prompt Caching Explained: Cut Repeated Input Costs by Around 90%
- Why Numbers, IDs, Dates and Emoji Use More Tokens Than You Think
- LLM API Pricing Compared: 22 Models From GPT-6 to Claude, Gemini and DeepSeek
Paste a sample of your document to see its tokens and cost per question.
Open the token counter →