 TokenSave
DeepSeek V4.1 Flash API Pricing: Peak vs Off-Peak, and How It Compares
Jonhisking · October 6, 2026
DeepSeek released V4.1 Flash in September 2026, and it replaced V4 Flash outright: the old deepseek-v4-flash model name still works, but it now runs V4.1 Flash. The headline is the price. Outside peak hours it is half the old V4 Flash price, and cached input costs almost nothing. Here is the full price table, when the cheap hours are, and how it compares with GPT-6 Luna, Gemini Flash and Claude Haiku.
DeepSeek V4.1 Flash API pricing
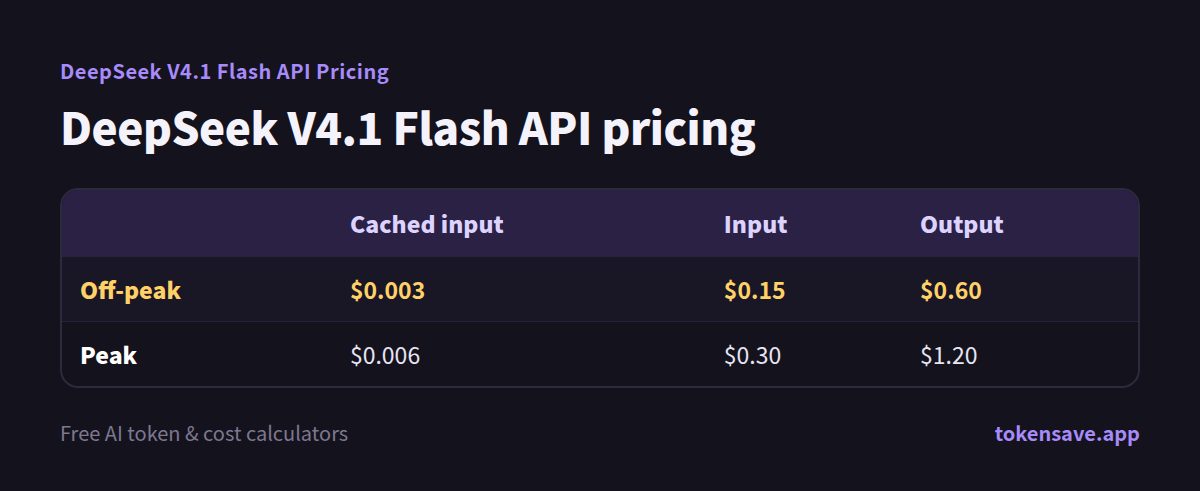
Per million tokens:
| Cached input | Input | Output | |
|---|---|---|---|
| Off-peak | $0.003 | $0.15 | $0.60 |
| Peak | $0.006 | $0.30 | $1.20 |
The peak price is the same as the old V4 Flash, so nobody pays more than before. The context window is 1 million tokens.
When are the cheap hours?
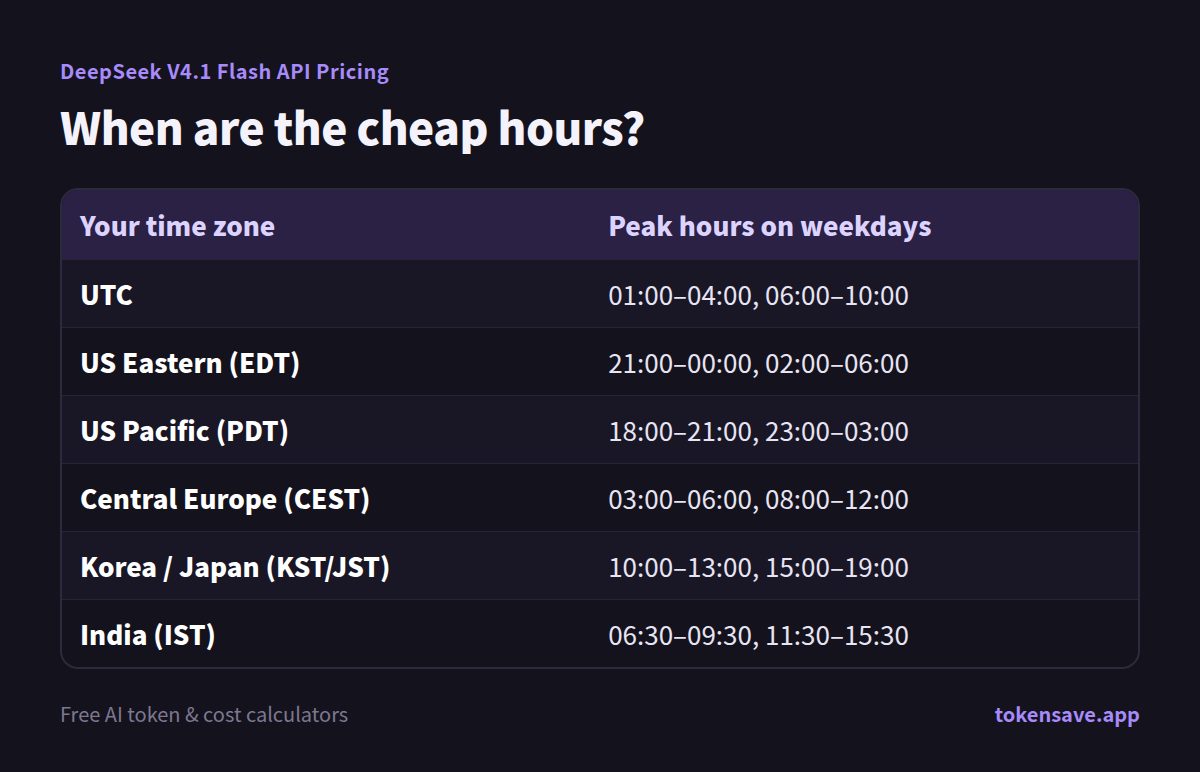
Peak hours are Monday to Friday, 01:00–04:00 and 06:00–10:00 UTC. Everything else, including all of Saturday and Sunday, is off-peak. That is 7 peak hours a weekday, so roughly 80% of the week is off-peak.
| Your time zone | Peak hours on weekdays |
|---|---|
| UTC | 01:00–04:00, 06:00–10:00 |
| US Eastern (EDT) | 21:00–00:00, 02:00–06:00 |
| US Pacific (PDT) | 18:00–21:00, 23:00–03:00 |
| Central Europe (CEST) | 03:00–06:00, 08:00–12:00 |
| Korea / Japan (KST/JST) | 10:00–13:00, 15:00–19:00 |
| India (IST) | 06:30–09:30, 11:30–15:30 |
In the Americas the first window falls on the evening before, Sunday to Thursday local time.
For work that can wait, such as overnight batch jobs, data cleanup or evaluations, schedule it outside these hours and every token costs half.
How it compares
A typical request of 2,000 input and 500 output tokens of English, no caching:
| Model | Input / output per 1M | 1 request | 10,000 requests |
|---|---|---|---|
| GPT-6 Luna | $0.10 / $0.50 | $0.00045 | $4.50 |
| DeepSeek V4.1 Flash (off-peak) | $0.15 / $0.60 | $0.00060 | $6.00 |
| DeepSeek V4.1 Flash (peak) | $0.30 / $1.20 | $0.00120 | $12.00 |
| Gemini 3.1 Flash-Lite | $0.25 / $1.50 | $0.00119 | $11.88 |
| Gemini 3.8 Flash | $0.75 / $3.75 | $0.00321 | $32.06 |
| DeepSeek V4 Pro | $1.32 / $3.96 | $0.00462 | $46.20 |
| Claude Haiku 4.5 | $1 / $5 | $0.00473 | $47.25 |
Off-peak, V4.1 Flash costs half of Gemini 3.1 Flash-Lite per request and about an eighth of Claude Haiku 4.5. Only GPT-6 Luna is cheaper for this kind of request.
Where the cache price changes everything
At $0.003 per million cached tokens off-peak, re-reading context is practically free. That matters for:
- Agents and long conversations, which re-send the same context at every step.
- Chat over a fixed document set, where the same reference text leads every request.
Example: an agent step that re-reads 24,000 cached tokens, adds 1,000 new tokens and writes 800 costs about $0.0007 off-peak on V4.1 Flash. The same step costs $0.0124 on GPT-6.1 Sol with its own cache discount. DeepSeek also says cached context now stays stored for at least 72 hours, so the discount survives long gaps between requests.
Should you use it?
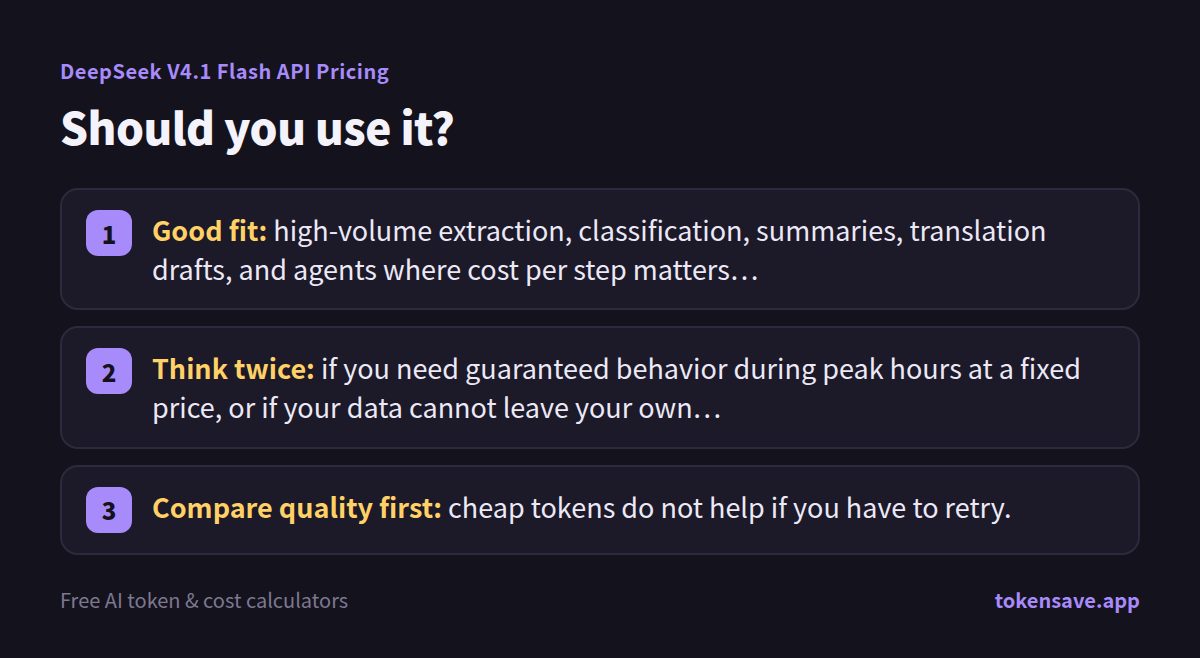
- Good fit: high-volume extraction, classification, summaries, translation drafts, and agents where cost per step matters more than the last bit of quality. Especially if your traffic is mostly outside the peak hours above.
- Think twice: if you need guaranteed behavior during peak hours at a fixed price, or if your data cannot leave your own region; check DeepSeek's data policy for your use case.
- Compare quality first: cheap tokens do not help if you have to retry. Run a sample of real requests through it and a model you trust.
Check your own prompt
Paste a prompt into the token counter and pick DeepSeek under "Others" to see its cost next to GPT, Claude and Gemini. More: The cheapest LLM APIs, ranked · DeepSeek V4 Flash vs GPT-6 Luna · Batch APIs: half-price AI.
Prices from DeepSeek's September 2026 announcement as reported by TechBriefly and Yotta Labs. Check DeepSeek's pricing page before you commit.
Sources
- DeepSeek API models and pricing
- DeepSeek: V4.1 Flash release (September 10, 2026)
- OpenAI API pricing
- Gemini API pricing
- Claude API pricing
More articles
- Claude Haiku vs Opus for Coding: 330 Measured Runs
- Claude Code Cache Lasts 1 Hour: What a Break Costs (Measured)
- How Many Tokens Do You Get with Claude Pro and Max?
- Claude Code vs Codex vs Cursor: Cost and a Real Test (2026)
- The Cheapest LLM APIs in 2026, Ranked by Real Cost per Request
Paste a prompt to see its tokens and cost on every GPT-6 model, Claude and Gemini.
Open the token counter →