 TokenSave
 Data · Dataset
Telling Claude Code to use subagents found nothing more and cost up to 221% more: 288 runs on subagent effort
Telling Claude Code to search with subagents did not find more of the answer, at any subagent effort. Across 288 runs on 12 “find every place” questions, the share of right answers found stayed between 97% and 100% in every condition; no condition moved it by as much as 2 points (pre-registered threshold: 15). The cost per run rose by 74% to 116% for Haiku 5.5 and by 143% to 221% for Opus 5.5, and every subagent ran on the same model as the main agent.
Measured 2026-11-06 · 288 runs · 12 questions · 6 repos · Claude Code 2.1.318 · License CC BY 4.0
DOI 10.5281/zenodo.24014489 · Also on Hugging Face · GitHub
Estimate your own Claude Code or Codex bill → See the monthly cost of Claude Code and Codex for your usage: API per task vs Claude and ChatGPT plans. Free, no sign-up.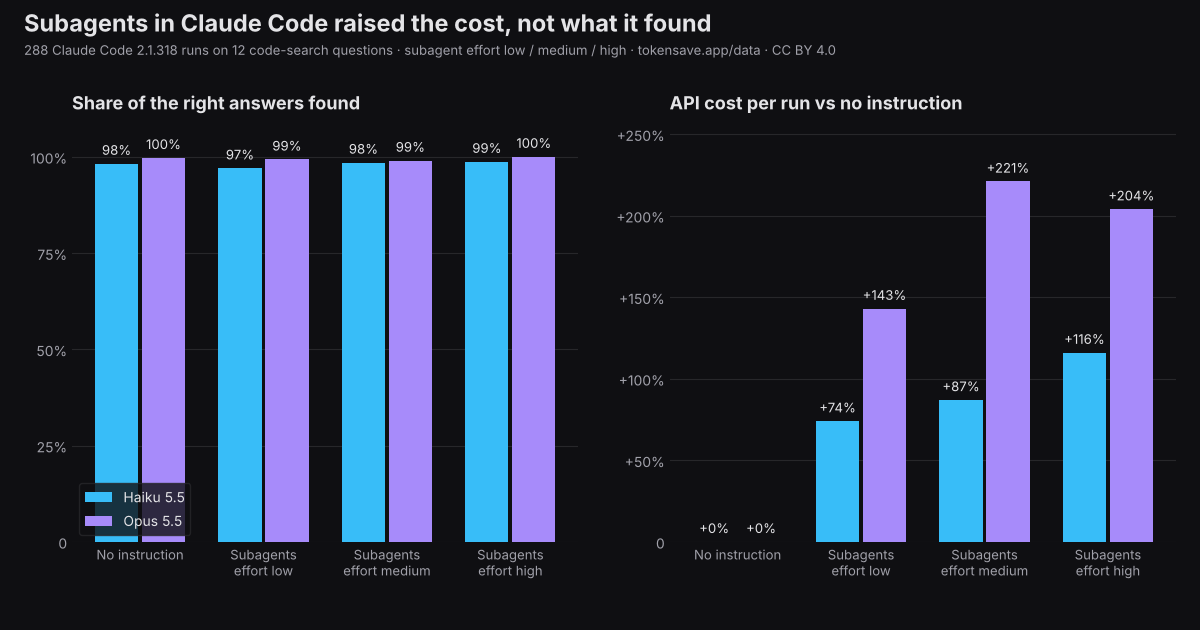
Key findings
- Subagents found nothing more. Share of the right answers found (mean per question), no instruction / subagents at effort low / medium / high: Haiku 5.5 98% / 97% / 98% / 99%; Opus 5.5 100% / 99% / 99% / 100%. Both models were near the ceiling without any instruction, so there was little room to gain.
- They cost more. Mean API cost per run, same order: Haiku $0.0056 / $0.0098 / $0.011 / $0.012 (+74%, +87%, +116%); Opus $0.16 / $0.39 / $0.51 / $0.48 (+143%, +221%, +204%). Median time per run: Haiku 18s to 37–48s, Opus 22s to 47–60s.
- Higher subagent effort did not mean better searches. For Opus, medium cost more than high; for both models, recall at high was within a point of low. The effort setting changed the bill more than the result.
- The Explore subagent ran on the main model. Every subagent call in every run used the same model as the main agent: Haiku called Haiku and Opus called Opus. On Opus, “use subagents” means paying Opus prices twice.
- Nobody used subagents unasked. With no instruction, 0 of 72 runs called a subagent (and 0 of 504 runs in dataset 26).
- Headless runs answer late. In 2.1.318 the Explore agent runs in the background, so a headless run emits several
resultevents: first a note that the agent is still searching, then the answer, sometimes a final “stopped the autonomous loop” note. 211 of 216 subagent runs had more than oneresult, and in 210 of them the first one held no answer. A script that reads only the first result would have found 6%–9% of the answers for Haiku and 0%–3% for Opus. 4 Haiku runs gave the answer and then never exited (20-minute timeout).
Totals by model and condition
Found = share of the answer key named in the answer, averaged per question (the pre-registered outcome, with amendment 2). Interval: 95%, from resampling questions. Last result only = the original pre-registered reading. First result only = what a script reading the first result event would get. 36 runs per row.
| Model · condition | Found | vs none, 95% interval | Last result only | First result only | Subagent calls | Cost/run | Cost change | Median s |
|---|---|---|---|---|---|---|---|---|
| Haiku 5.5 · No instruction | 98% | – | 98% | 98% | 0.0 | $0.0056 | – | 18 |
| Haiku 5.5 · Subagents, effort low | 97% | −1.2 (−5.3 to +1.7) | 78% | 6% | 1.1 | $0.0098 | +74% | 37 |
| Haiku 5.5 · Subagents, effort medium | 98% | +0.3 (+0.0 to +0.9) | 97% | 9% | 1.2 | $0.011 | +87% | 36 |
| Haiku 5.5 · Subagents, effort high | 99% | +0.5 (+0.0 to +1.2) | 88% | 0% | 1.2 | $0.012 | +116% | 48 |
| Opus 5.5 · No instruction | 100% | – | 100% | 100% | 0.0 | $0.16 | – | 22 |
| Opus 5.5 · Subagents, effort low | 99% | −0.3 (−1.0 to +0.0) | 99% | 0% | 2.1 | $0.39 | +143% | 47 |
| Opus 5.5 · Subagents, effort medium | 99% | −0.7 (−2.1 to +0.0) | 99% | 3% | 2.0 | $0.51 | +221% | 58 |
| Opus 5.5 · Subagents, effort high | 100% | +0.3 (+0.0 to +1.0) | 100% | 1% | 2.1 | $0.48 | +204% | 60 |
Question by question
C0 no instruction, C1–C3 subagents at effort low, medium, high. 3 runs per cell. Items = entries in the answer key.
| Repo · question | Items | Haiku C0 | Haiku C1 | Haiku C2 | Haiku C3 | Opus C0 | Opus C1 | Opus C2 | Opus C3 |
|---|---|---|---|---|---|---|---|---|---|
| undici · In this repository's library code (lib/), find every place where a RequestAbortedError is created | 16 | 98% | 77% | 98% | 100% | 96% | 92% | 88% | 100% |
| undici · In this repository's library code (lib/), find every place where a HeadersTimeoutError or a BodyTimeoutError is created | 4 | 100% | 100% | 100% | 100% | 100% | 100% | 100% | 100% |
| fastify · In this repository's library code (lib/), find every place outside lib/errors.js that throws or returns one of the content-type-parser errors (the FST_ERR_CTP_* codes) | 12 | 100% | 100% | 100% | 100% | 100% | 100% | 100% | 100% |
| fastify · In this repository's library code (lib/), find every place outside lib/errors.js that throws or returns one of the hook errors (the FST_ERR_HOOK_* codes) | 3 | 100% | 100% | 100% | 100% | 100% | 100% | 100% | 100% |
| cachetools · In this library, list every class that defines its own __setitem__ or popitem method | 14 | 100% | 100% | 100% | 100% | 100% | 100% | 100% | 100% |
| cachetools · In this library's source code, find every method or function that calls expire() | 9 | 89% | 96% | 93% | 93% | 100% | 100% | 100% | 100% |
| markdown · In this package's source (the markdown/ directory), find every place that registers a tree processor (treeprocessors.register) | 8 | 100% | 100% | 100% | 100% | 100% | 100% | 100% | 100% |
| markdown · In this package's source (the markdown/ directory), list every class that subclasses an InlineProcessor class (directly, by naming a class ending in InlineProcessor as its base) | 20 | 100% | 100% | 100% | 100% | 100% | 100% | 100% | 100% |
| anyio · In this library's source code (src/), find every place that raises BrokenResourceError | 25 | 100% | 99% | 100% | 100% | 100% | 100% | 100% | 100% |
| anyio · In this library's source code (src/), list every class that implements an aclose() method | 28 | 100% | 100% | 100% | 100% | 100% | 100% | 100% | 100% |
| zod · In zod's v4 core (packages/zod/src/v4/core, excluding tests), find every place that reads the coerce option of a schema definition | 4 | 92% | 92% | 92% | 92% | 100% | 100% | 100% | 100% |
| zod · In zod's v4 source (packages/zod/src/v4, excluding tests), find every place that throws $ZodAsyncError, the error raised when a Promise shows up during synchronous parsing | 8 | 100% | 100% | 100% | 100% | 100% | 100% | 100% | 100% |
The four conditions
- No instruction: the question only.
- Subagents, effort low / medium / high: the question plus “Use subagents (the Explore agent) for the searching, in parallel where it helps, and write the final answer yourself.”, with
CLAUDE_CODE_SUBAGENT_EFFORTset to low, medium or high. The main agent stayed at its default effort.
Method
- Pre-registered on 2026-11-06 before the first scored run: PREREG.md, with the answer key’s sha256. Two amendments are dated in the file; the second was made after the condition table had been seen, so both readings are published.
- Questions: 12 “find every place” searches, 2 each in undici, fastify, cachetools, Python-Markdown, anyio and zod at fixed commits. The answer key came from a regex over the source and a parser for the enclosing function or class: 151 items, 3 to 28 per question.
- Agent: Claude Code 2.1.318 on one Windows 11 laptop, headless (
-p), read and search tools only (Edit, Write, Bash, WebFetch and WebSearch disallowed), no MCP servers. 3 runs per question, model and condition, in a shuffled order, 2 at a time. - Scoring: an item counts when the answer names its file and its function or class. The answer is the text of all
resultevents of the run. - Cost is Claude Code’s own per-run figure at API prices; the runs were made on a subscription. 40 runs first hit the subscription’s 5-hour limit and a login expiry; they gave no answer and were re-run.
Limitations
- Both models found almost everything with no instruction. A gain had little room; on harder searches subagents might help.
- The repos are mid-sized. In a large monorepo, parallel subagents might save context or time.
- One prompt wording, one Claude Code version (2.1.318), 3 runs per cell and 12 questions.
- The key is regex-based: a correct item the regex missed is not credited, and an extra item in the answer is not penalised.
How to cite
Free to use, quote and republish with attribution under CC BY 4.0. Please link to this page.
TokenSave (2026). Telling Claude Code to use subagents found nothing more and cost up to 221% more: 288 runs on subagent effort [Data set]. Zenodo. https://doi.org/10.5281/zenodo.24014489
BibTeX
@misc{tokensave_claude_subagent_effort_2026,
  author    = {{TokenSave}},
  title     = {Telling Claude Code to use subagents found nothing more and cost up to 221\% more: 288 runs on subagent effort},
  year      = {2026},
  publisher = {Zenodo},
  doi       = {10.5281/zenodo.24014489},
  url       = {https://doi.org/10.5281/zenodo.24014489},
  note      = {Dataset, CC BY 4.0}
}
Embed the chart
Related
- Edge-case prompts and effort: 504 runs (dataset 26)
- Claude effort levels: tokens, time and cost
- Claude Haiku vs Opus on 25 real bugs
- Estimate your own Claude Code or Codex bill
Questions or corrections: contact@jonhisking.com